
ITHome October 8 news: At the event held in San Francisco, USA, at 10 a.m. Pacific Time on October 7 (1 a.m. Beijing Time on October 8), Microsoft announced that GitHub Copilot will support local AI model inference by the end of this month,and developers can automatically or manually switch between cloud models and on-device models.
GitHub Copilot is an AI programming assistant launched by Microsoft that can be integrated into tools such as Visual Studio Code and the CLI, generating completion, explanation, or refactoring suggestions based on code context.
GitHub Copilot currently relies on cloud-hosted models, with an orchestrator routing requests based on performance, cost, and accuracy. Microsoft plans to expand this mechanism by the end of this month, allowing Copilot to automatically choose between cloud models and local AI models, coordinating inference tasks in the background.
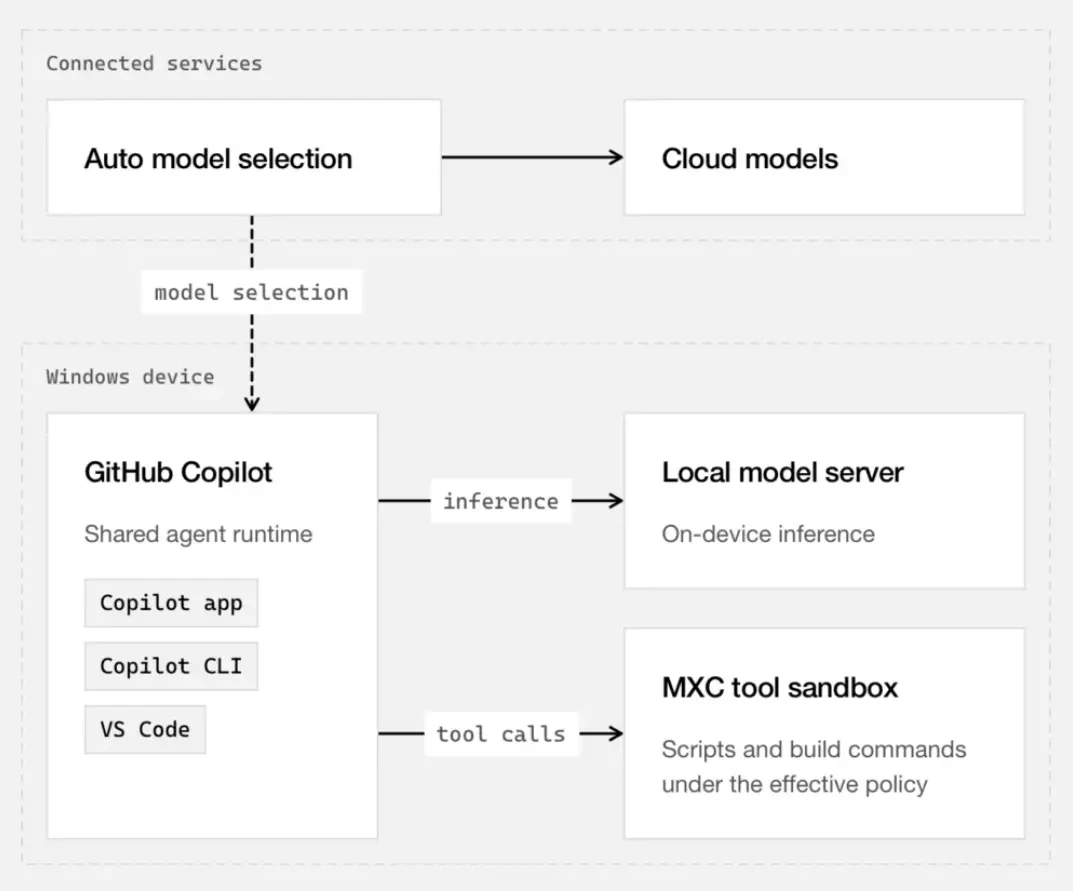
Microsoft offers GitHub Copilot users two modes: automatic orchestration or forced use of the on-device model. Users can set their preferences in GitHub Copilot CLI, the Copilot app, and Visual Studio Code.
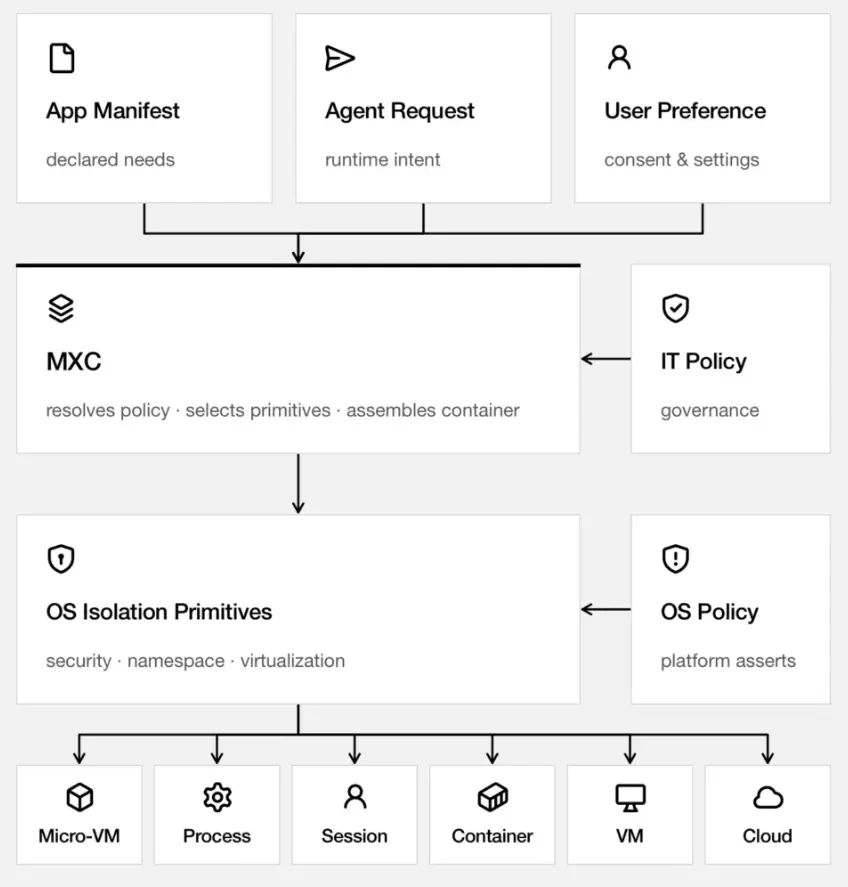
Local model selection supports specifying a provider, model, or endpoint; developers can select MAI Code 1.1 Flash through Windows ML, or connect an OpenAI-compatible local endpoint and use the models it exposes.
Microsoft launched the MAI Code 1.1 Flash "mixture of experts" model with a total of 137 billion parameters and 6.8 billion active parameters, using quantization and speculative decoding technologies to optimize response speed and memory usage.
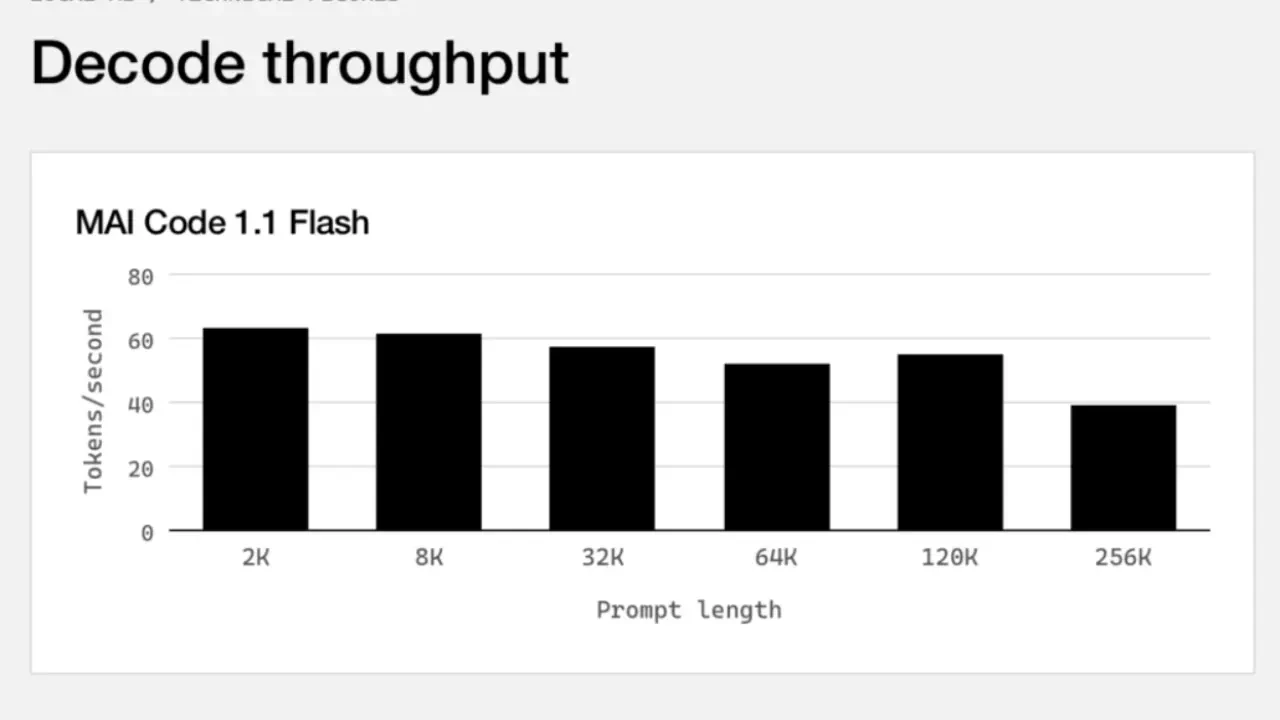
Real-world testing of the model on the Surface Laptop Ultra showed significant improvements in peak memory usage, token utilization, and processing speed in complex tasks. Decoding throughput tests showed that with prompt lengths from 2K to 256K tokens, throughput ranged between 40 and 63 tokens per second. ITHome attaches the related images below:
Microsoft Surface Laptop Ultra launch event special coverage