IT Home On October 12, Alibaba Qianwen officially released QwenGyre, a online reinforcement learning framework for long-term intelligent agent tasks.
According to official statements, when the agent undertakes complex tasks, a single execution often lasts several hours. There are hundreds of interdependent interactions between the model and the environment, and millions of tokens are processed in total. QwenGyre, through elastic scheduling and trajectory processing, turns such long-term tasks into effective training sources, while improving capabilities and efficiency.
QwenGyre can divide the GPU into several computing units. After each batch of tasks is completed, the empty units are transferred to training, just like who finishes first in a project team gets to participate in the review. The ongoing tasks remain undisturbed; their progress and status are preserved as they were. Even the previously calculated caches are completely removed, eliminating the need to start all over again. The newly available units are directly added to this round of training. Those who calculate faster work more, and finally, the core units summarize the results to complete one parameter update.
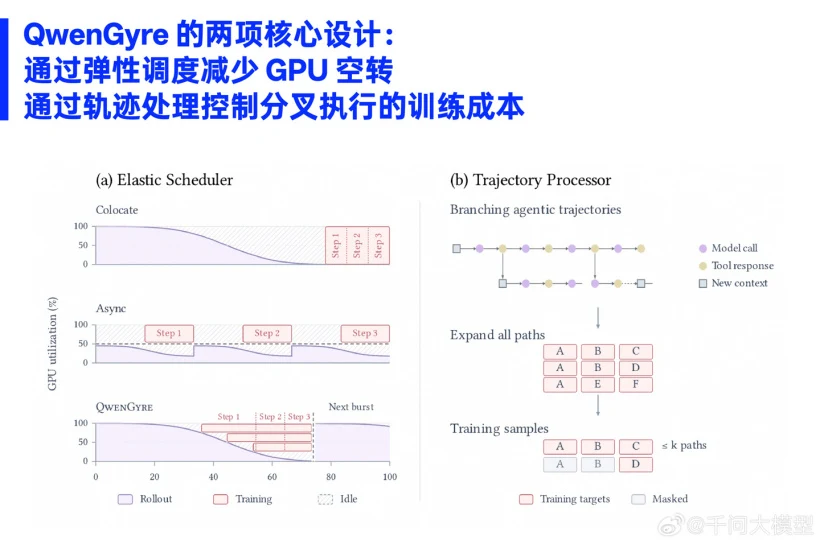
IT Home notes that QwenGyre can record the real context of each output generation using Token-in Token-out, organize it into a trajectory tree based on shared prefixes, and only expand the selected paths into training samples. At the same time, tasks that are completed partially but with a timeout can also provide useful feedback through Partial Scoring, without wasting any effort.
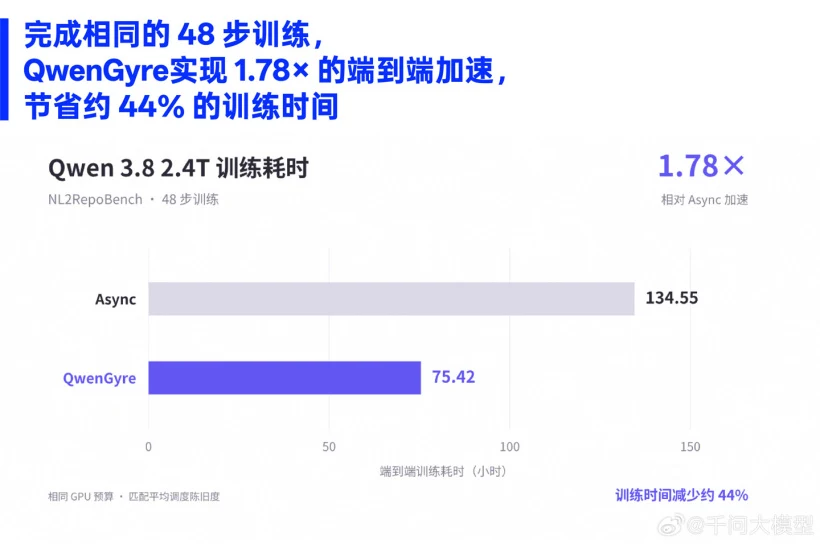
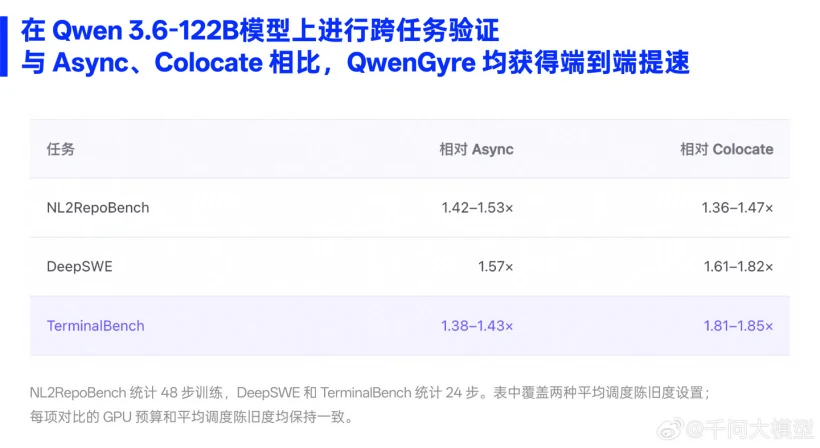
In terms of performance, in the NL2RepoBench online reinforcement learning experiment, training was conducted with a task involving approximately 700,000 tokens per rollout. After 48 steps of training, the model pass rate increased from 52.5% to 58.5%. Under the same GPU budget, QwenGyre achieved an end-to-end acceleration of 1.78× compared to Async, and the training scores were close to those of Async and Colocate. In cross-task validation on Qwen3.6-122B, all three tasks—NL2RepoBench, DeepSWE, and TerminalBench—experienced an end-to-end speedup.