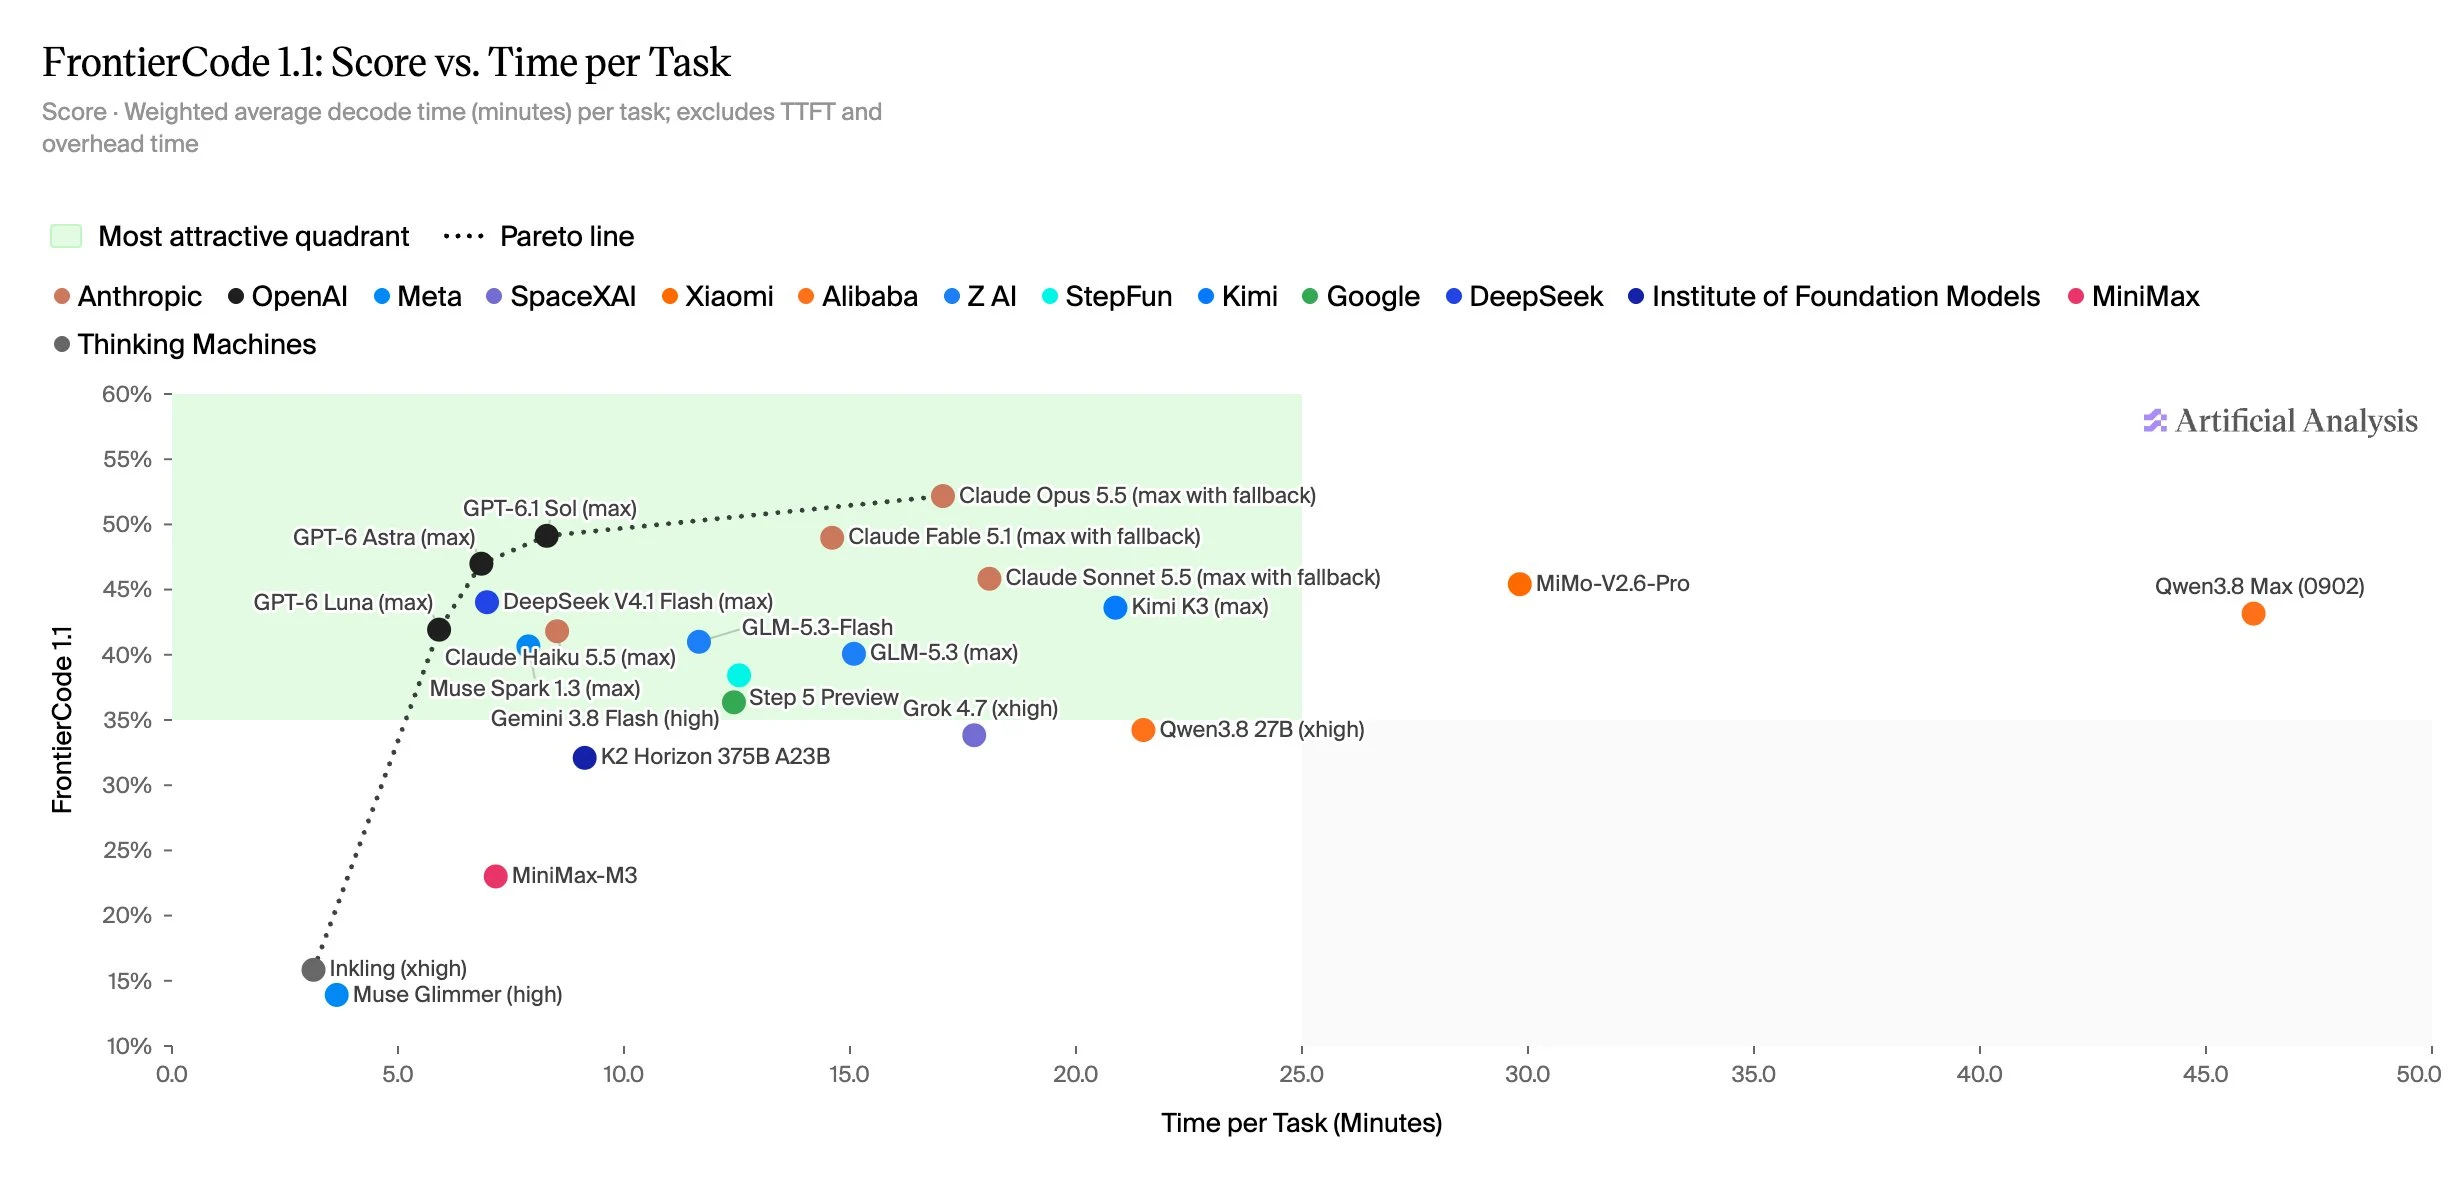
GPT-6 Luna (max), GPT-6 Astra (max), GPT-6.1 Sol (max) and Claude Opus 5.5 (max with fallback) sit on the Pareto frontier for score vs. Time per Task. We estimate Time per Task from each model's token usage and our live output speed measurements. The GPT-6 models are fast because they use few tokens, at 27k to 48k output tokens per task. DeepSeek V4.1 Flash (max) uses ~119k but is served quickly, averaging ~7 minutes per task, around 40% of the time of Claude Opus 5.5 (max with fallback) at ~17 minutes.