Text Arena battles show:
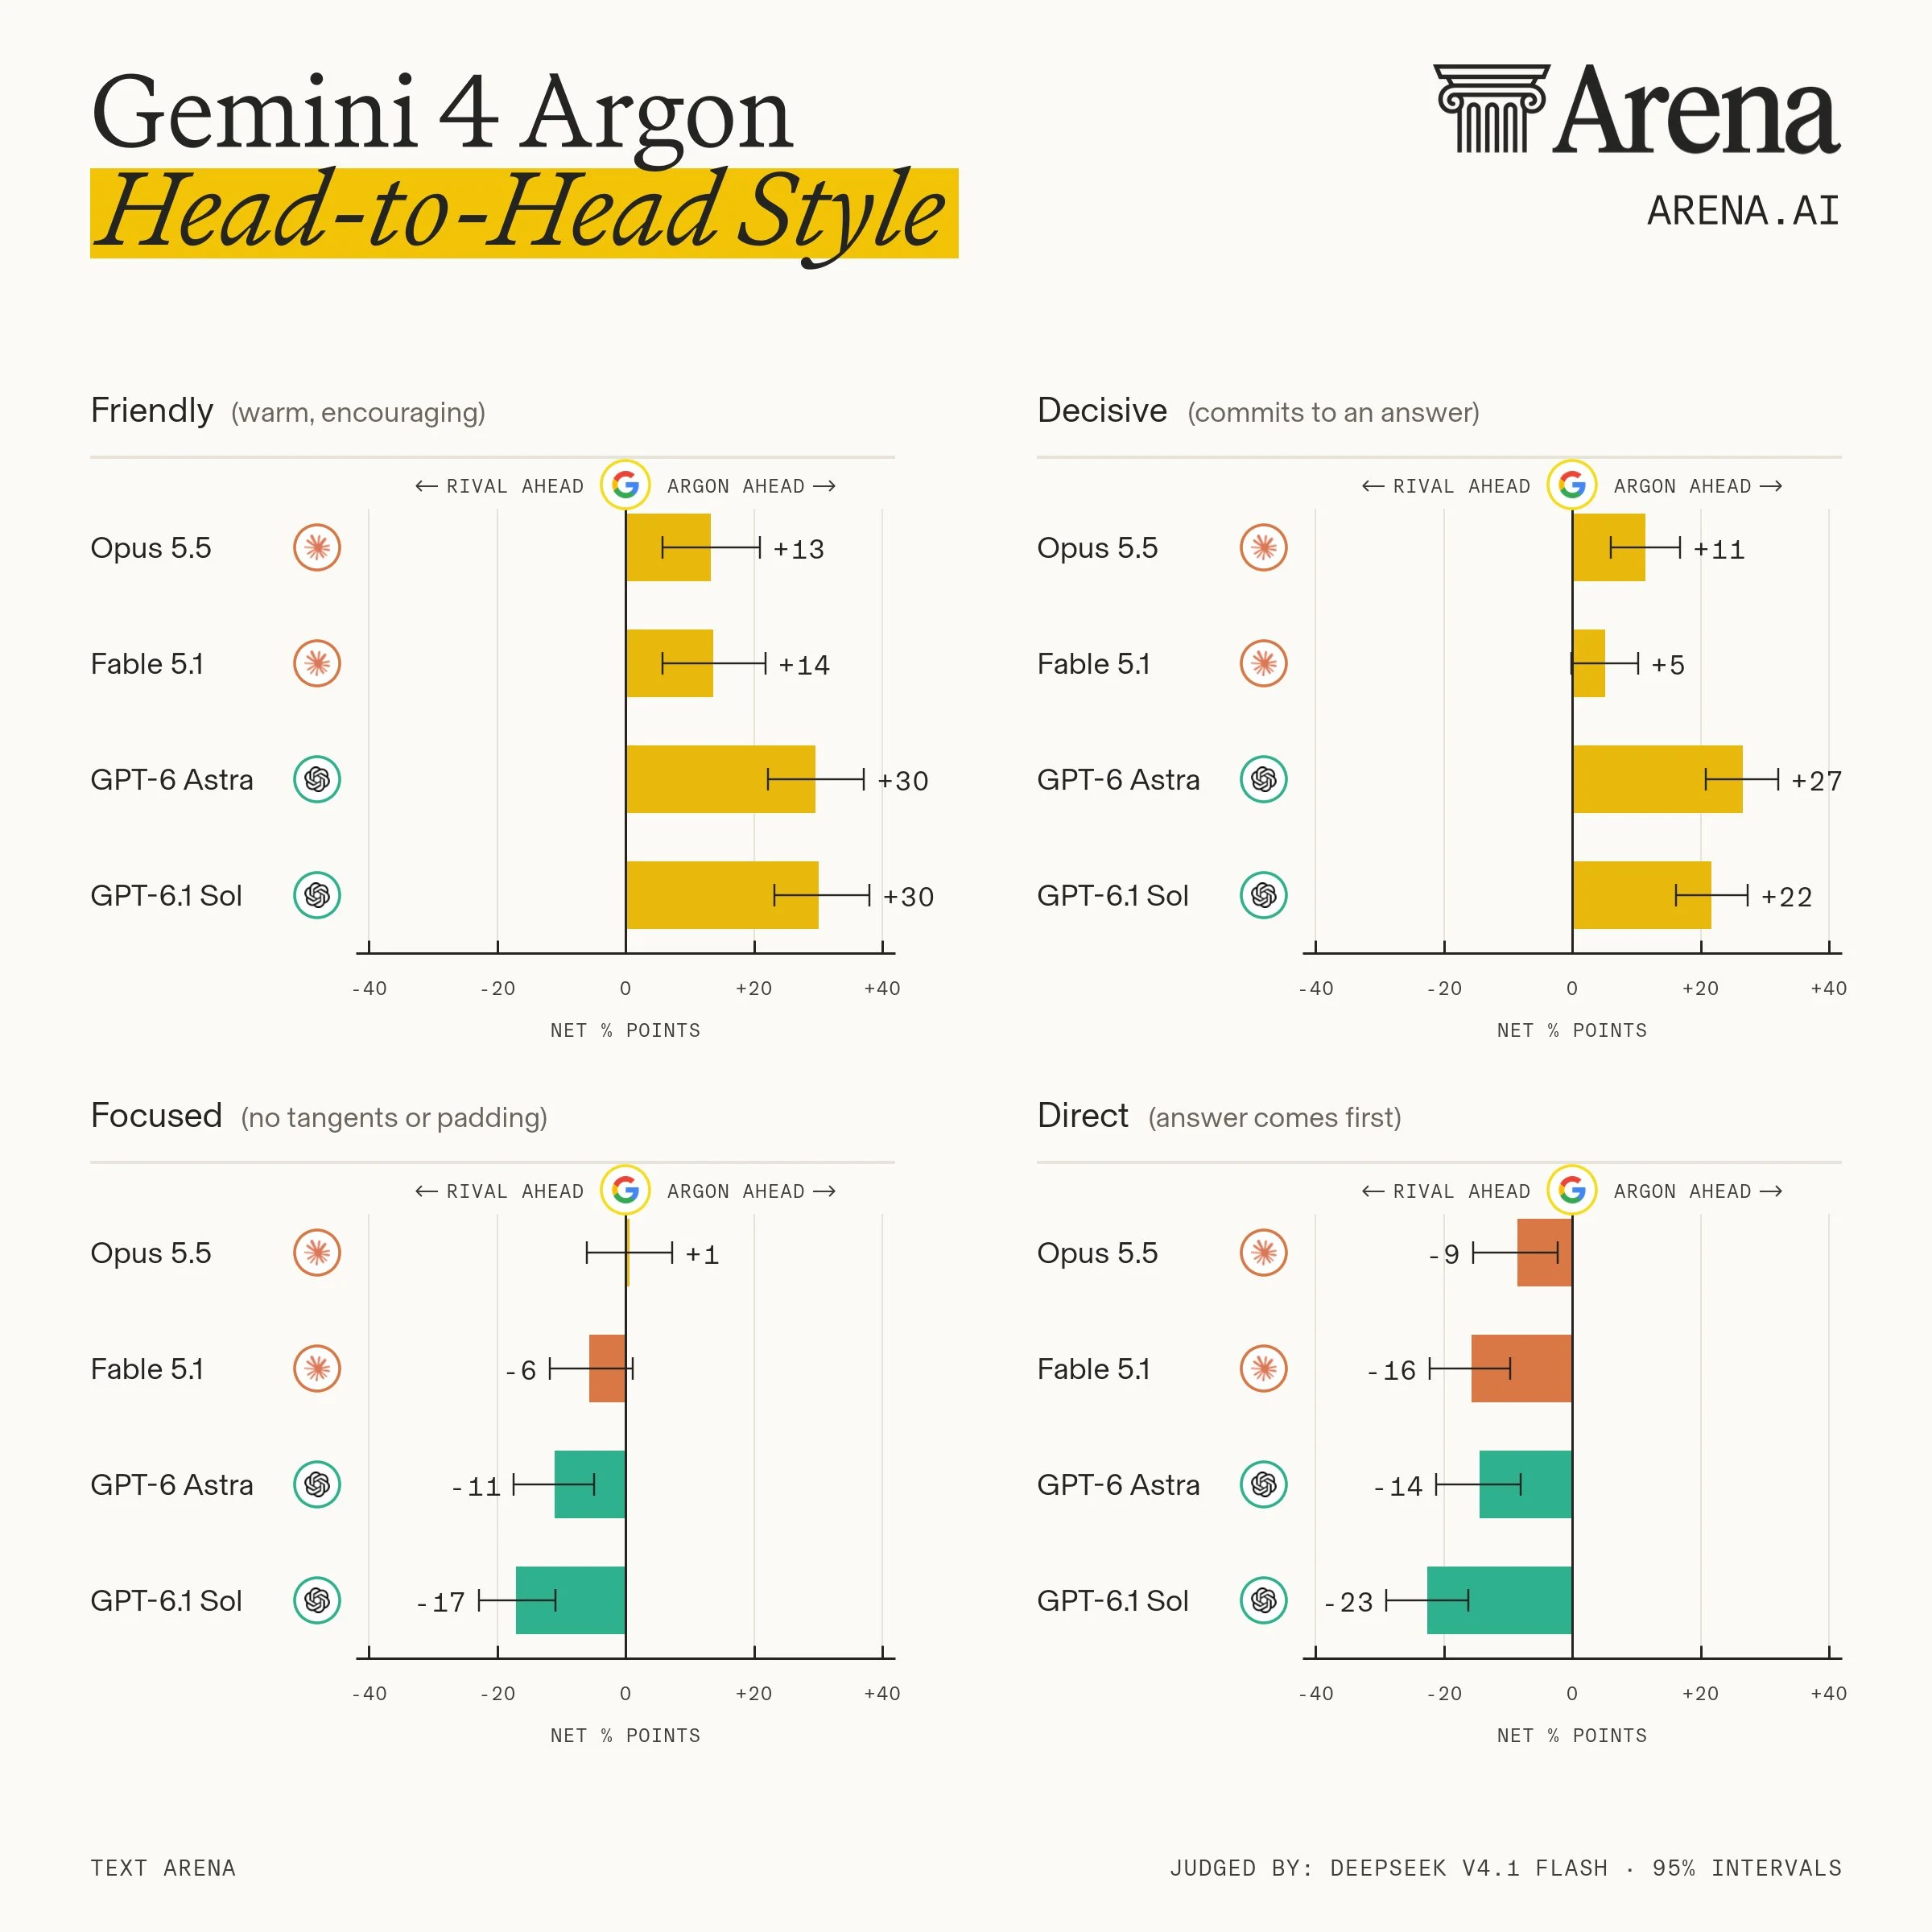
- @GoogleDeepMind's new release is more friendly and decisive. It keeps a warm, encouraging and clear tone. Against GPT-6.1 Sol, the AI judge rated Argon friendlier in 55% of comparisons and Sol in just 25%. Against Opus 5.5, it's 46% vs 32%.
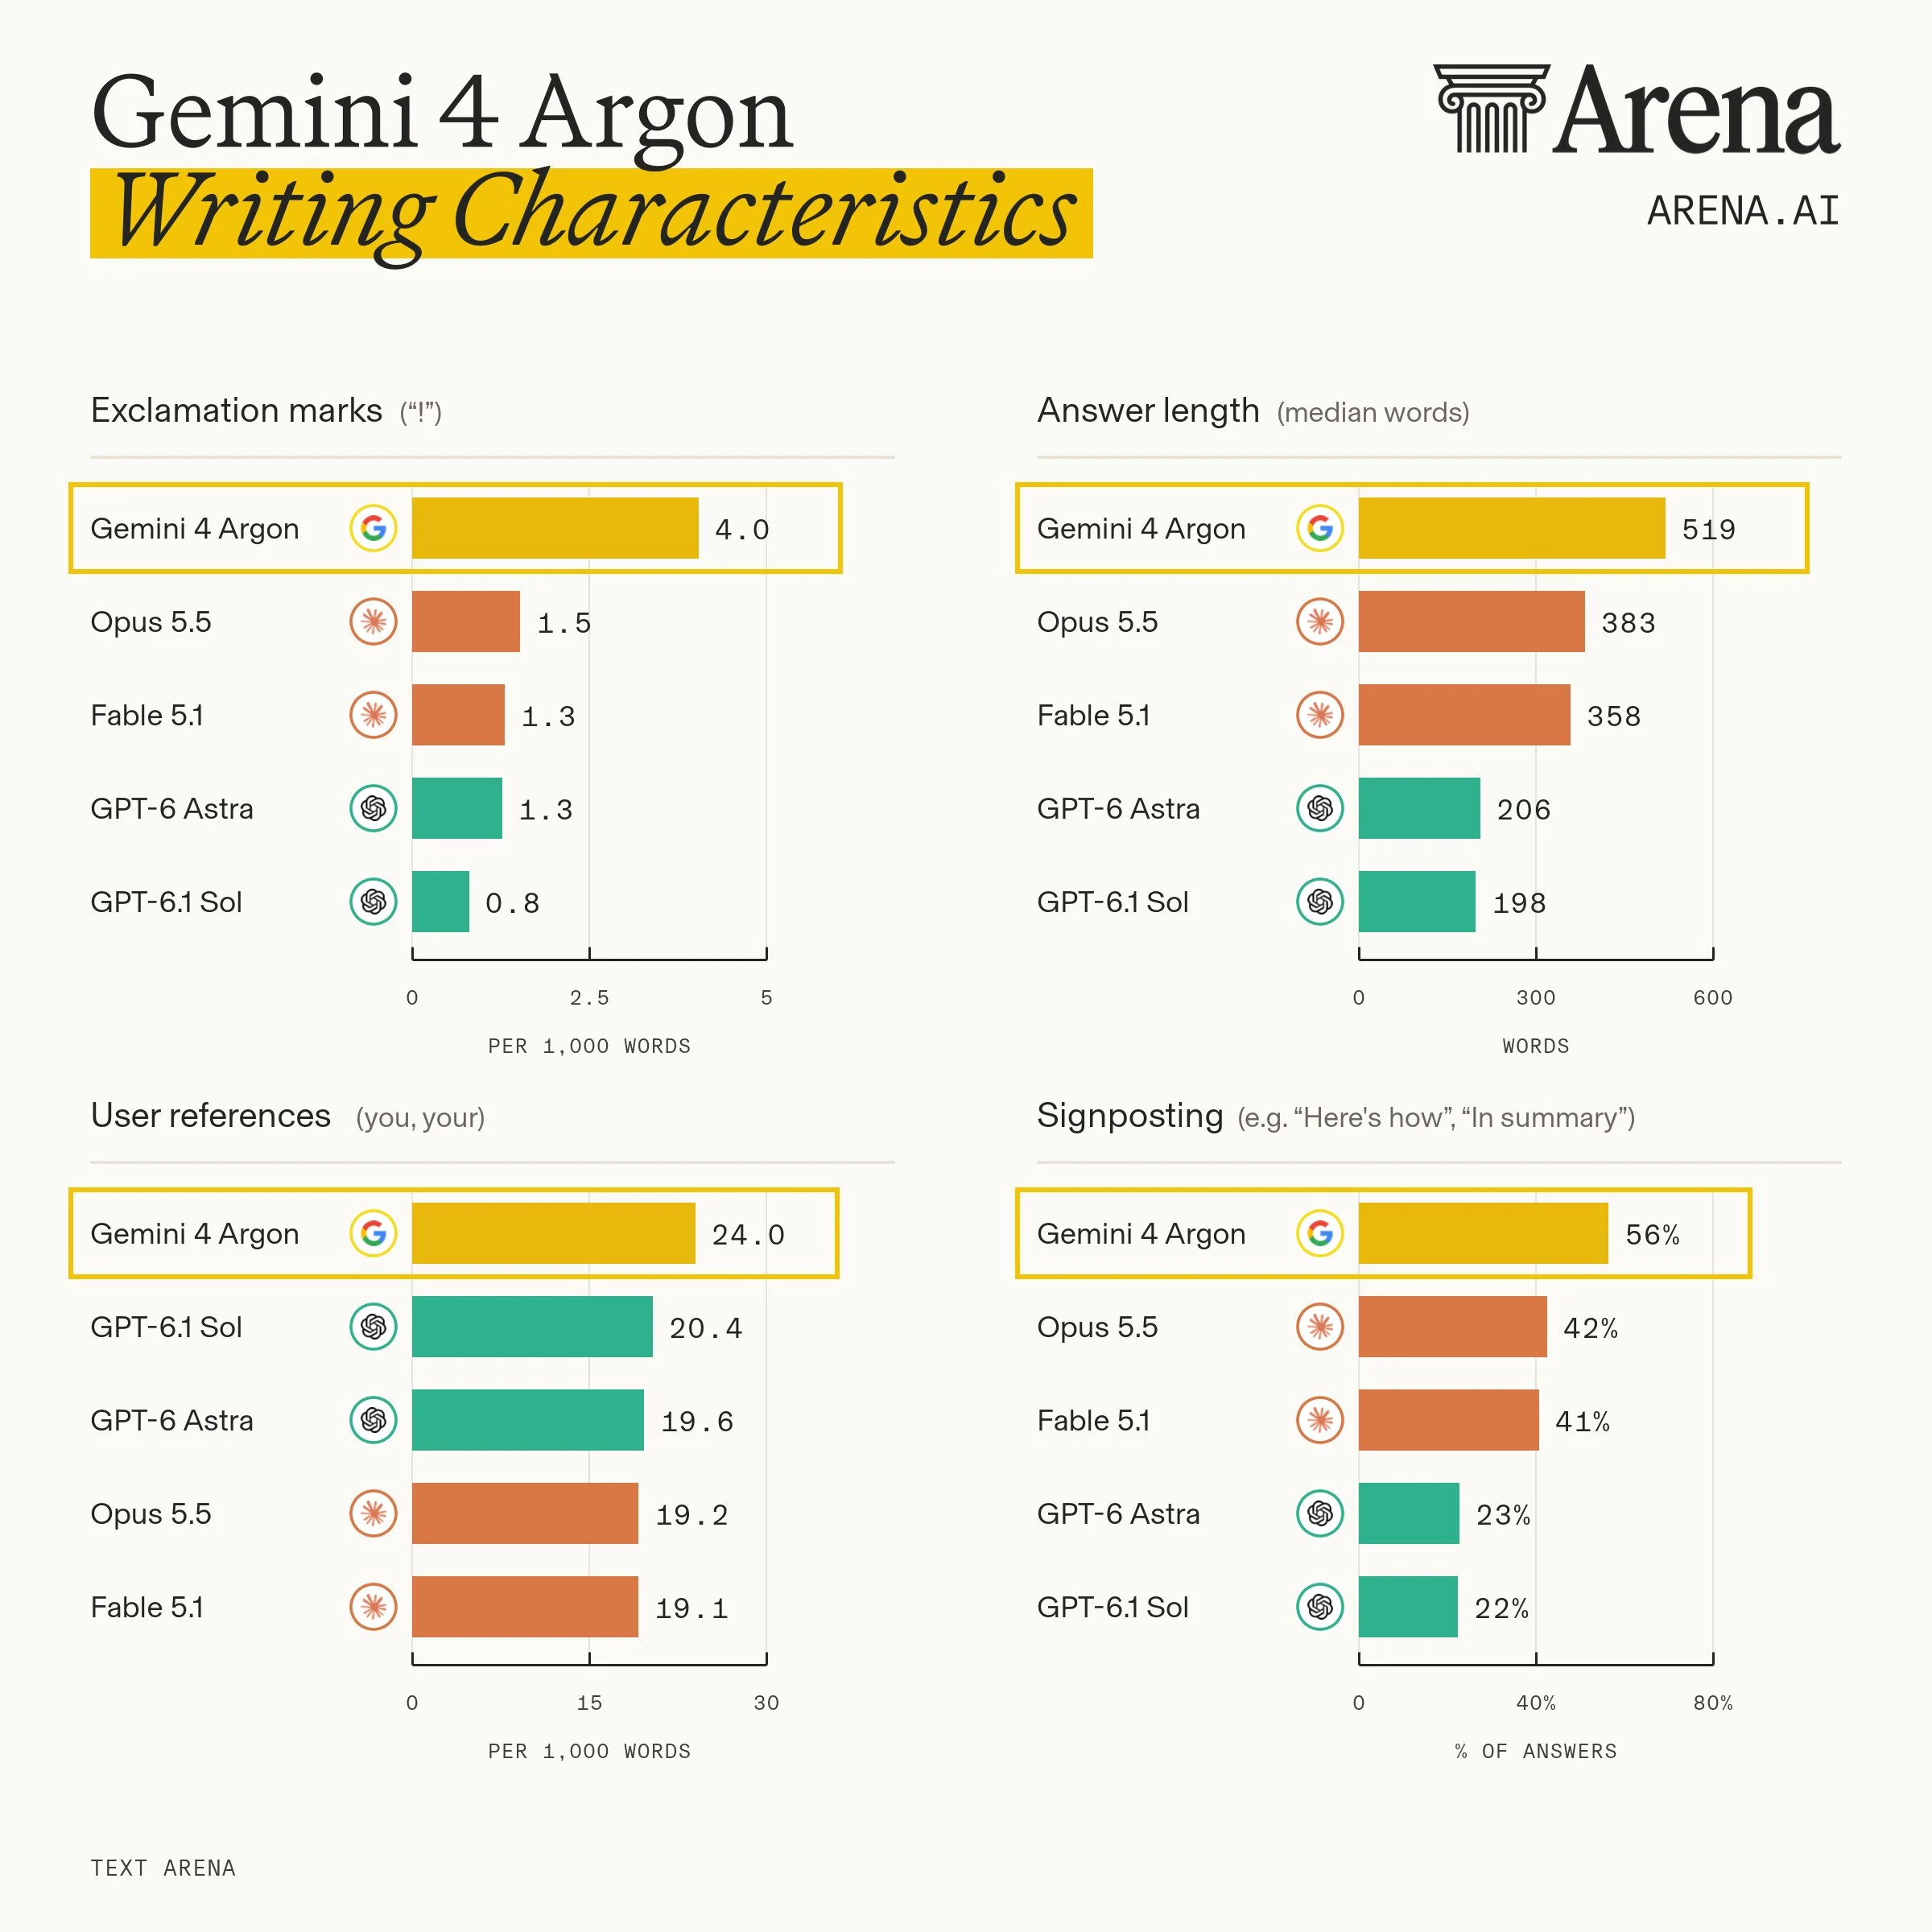
- It is more conversational: the model goes on tangents more, and is less direct. Rivals' answers were rated more direct in 32-37% of comparisons, Argon's in only 14-23%. This is also reflected in its answer length: the median Argon answer is 519 words, against 358-383 for Claude and about 200 for GPT models.
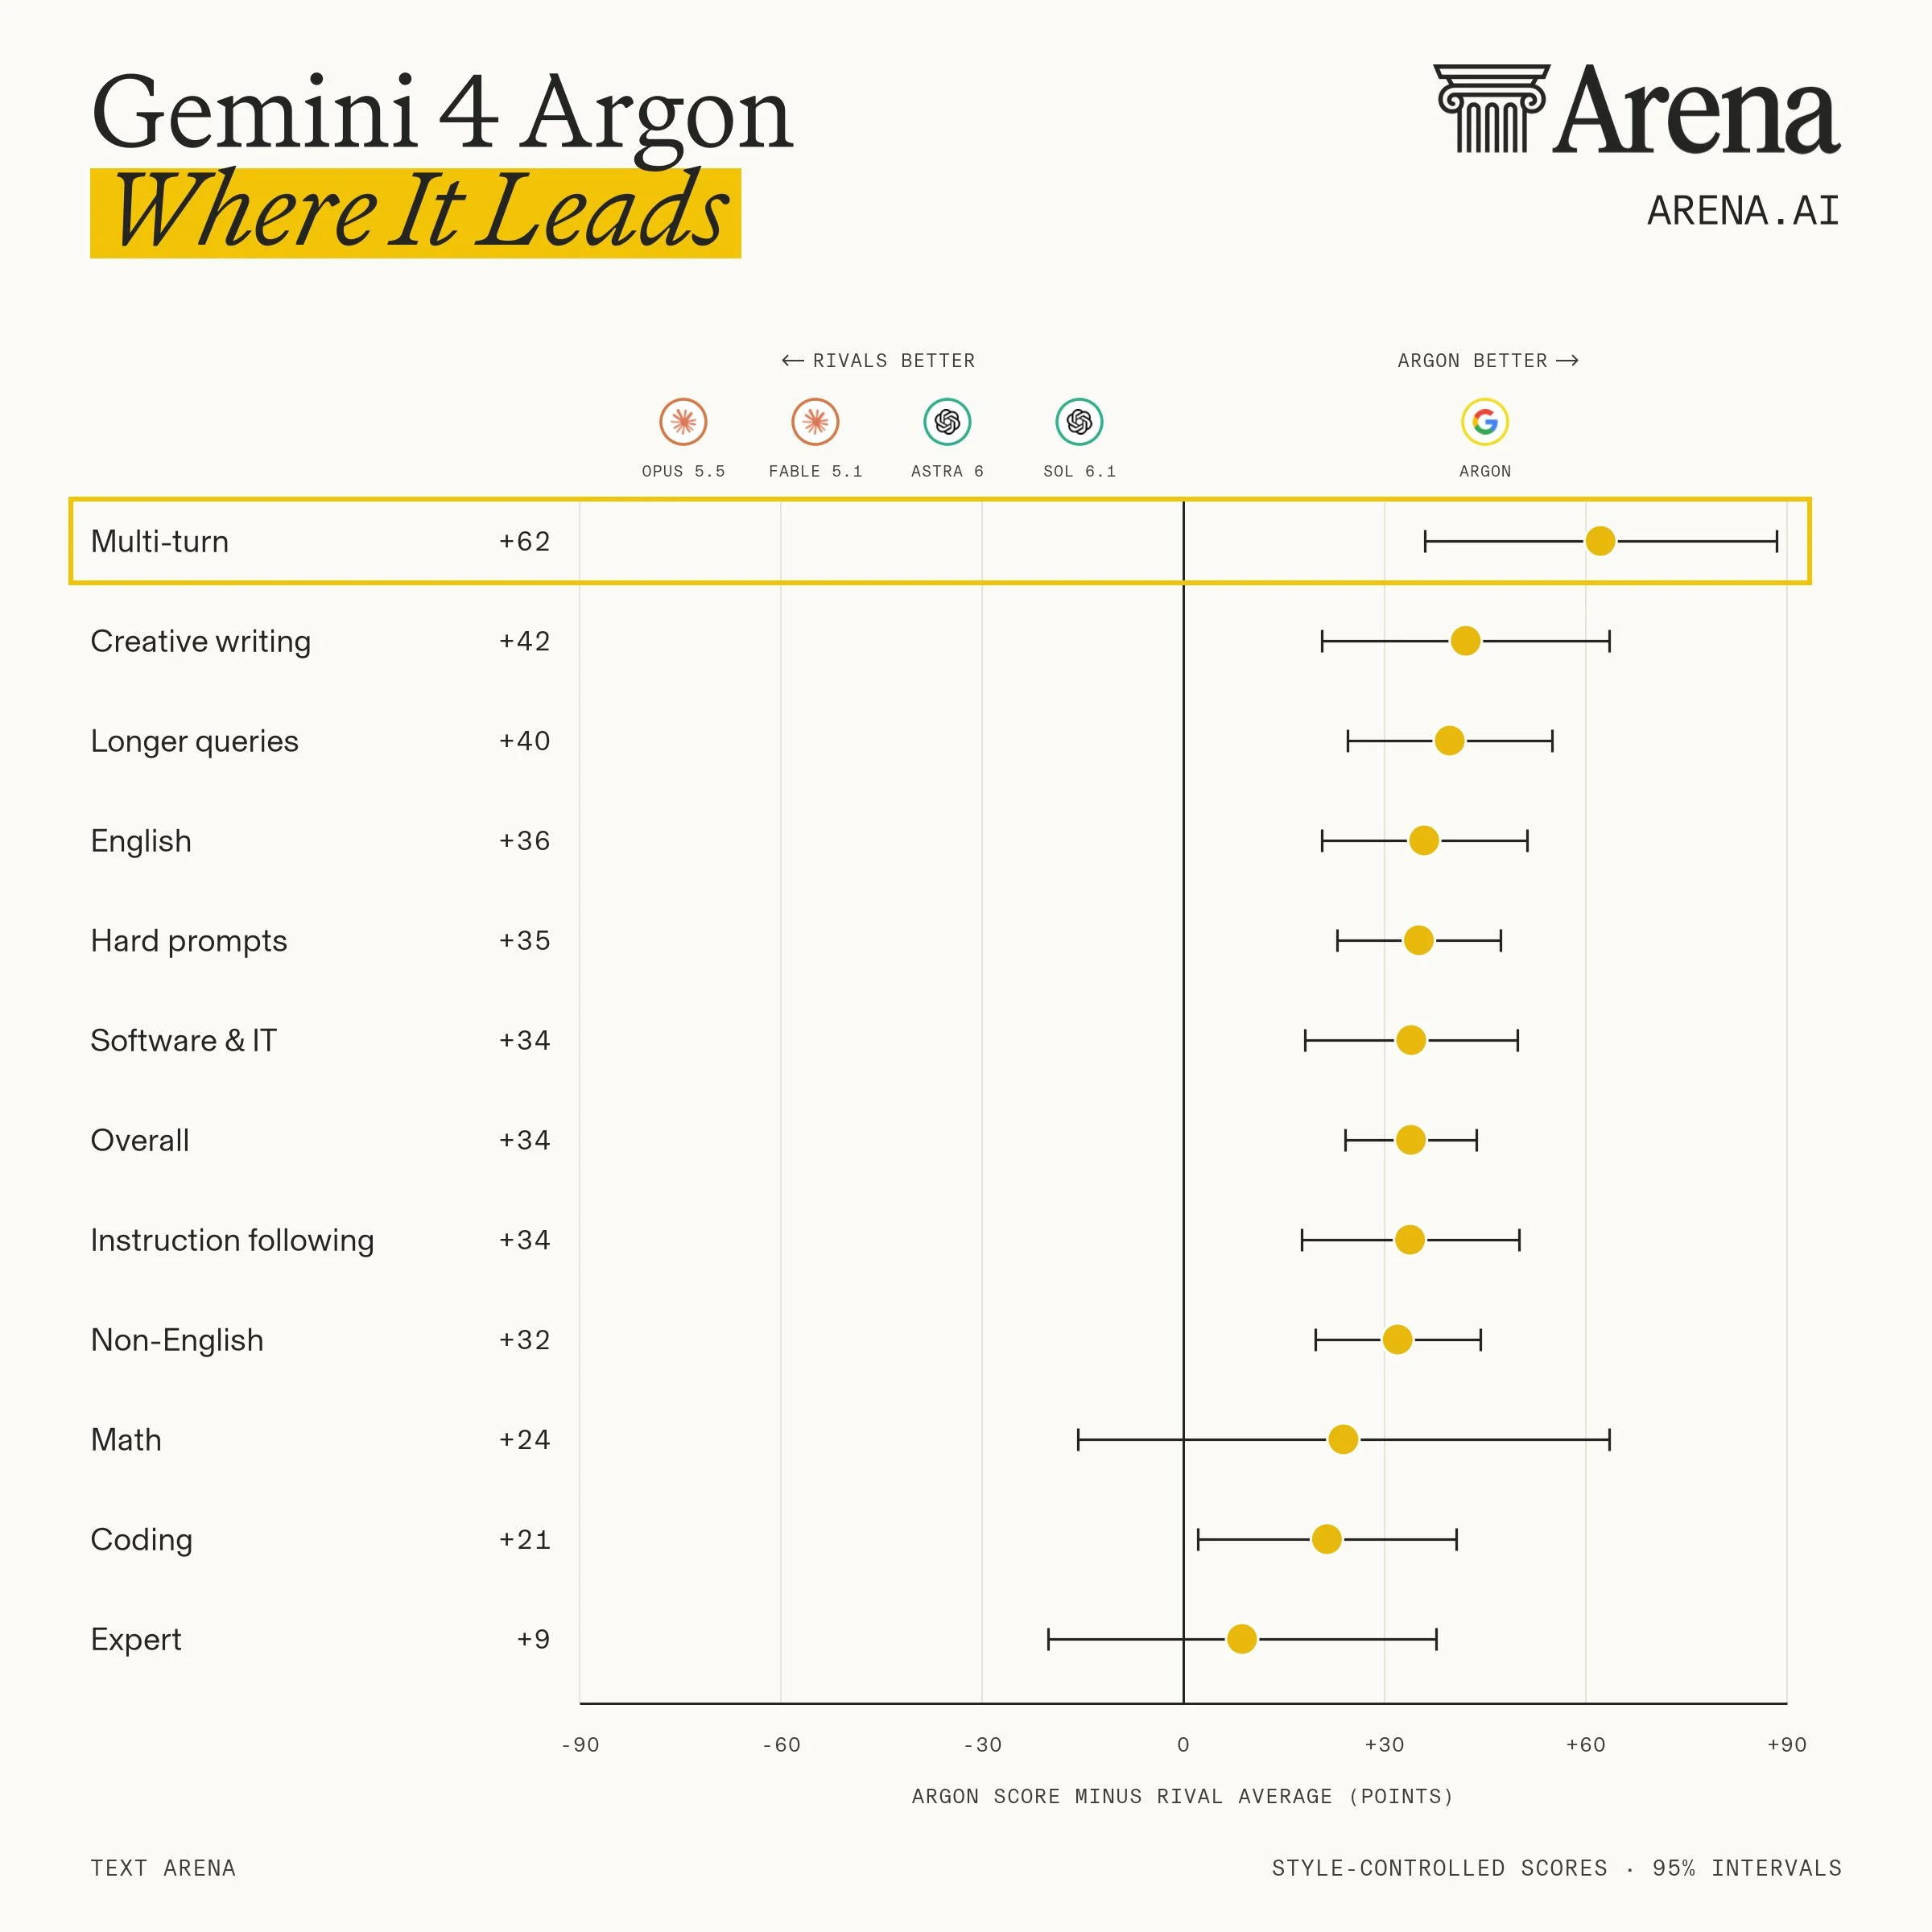
- These behaviors show up in user votes. Argon has the strongest advantage in multi-turn chats (+62 points), creative writing (+42) and longer queries (+40), the categories where such personality matters most.
- The clearest markers of its approachable style are its use of exclamation marks (about 3x Opus 5.5 and 5x GPT-6.1 Sol), references to the user (24 per 1,000 words, against 19-20 for every rival), and signposting (56% of its answers, against 41-42% for Claude and 22-23% for GPT models).