
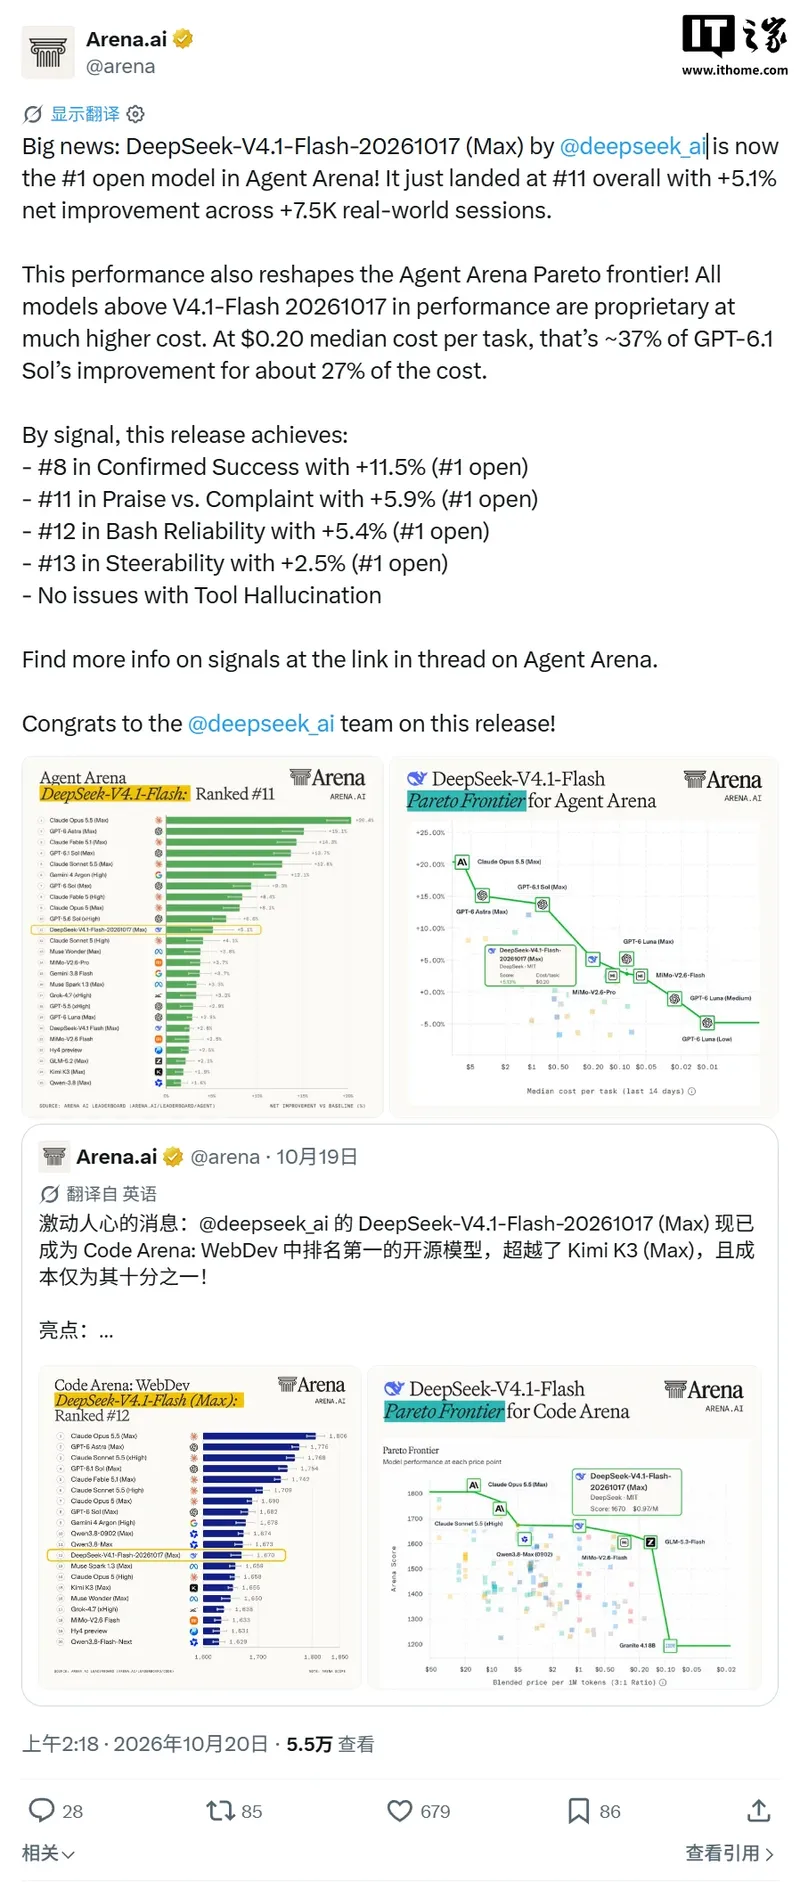
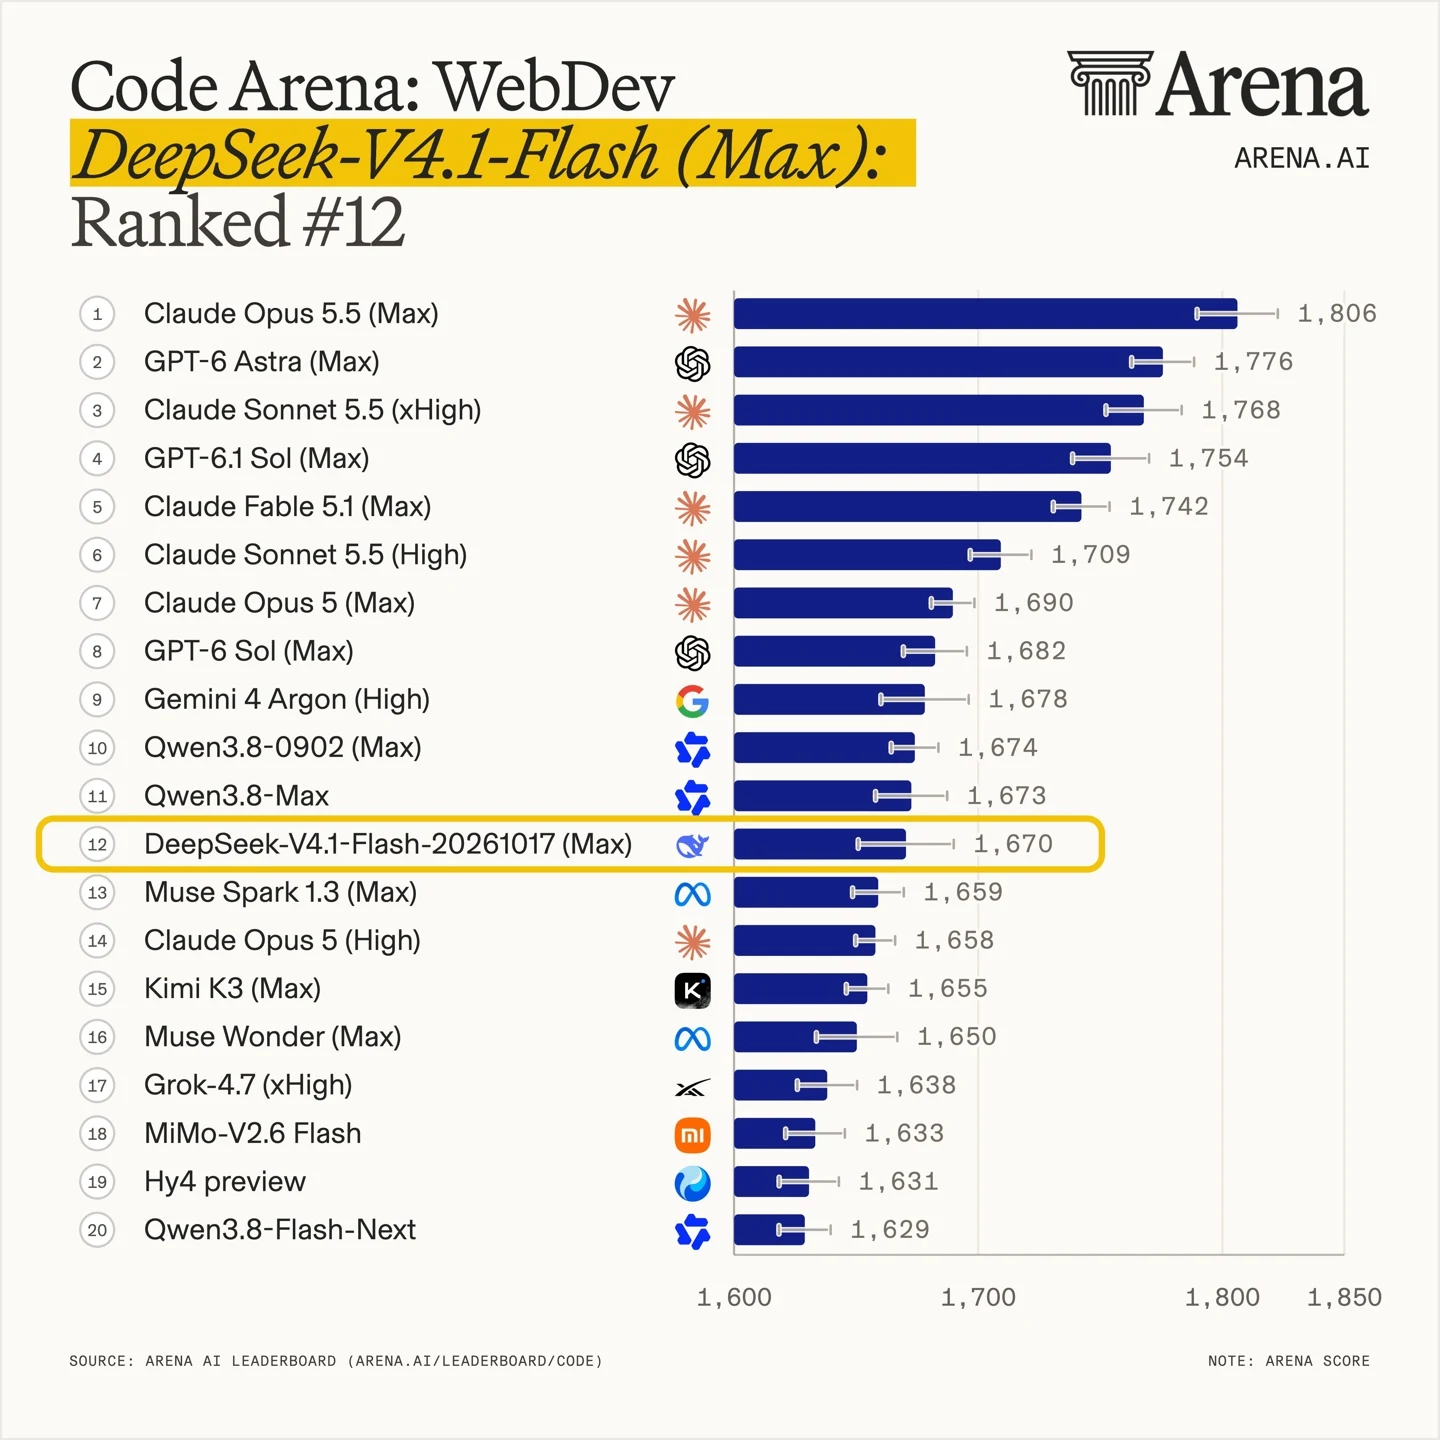
IT Home On October 20, AI Arena announced that DeepSeek-V4.1-Flash-1017, recently released by DeepSeek, reached the top of both the Agent Arena and the Code Arena: WebDev open-source model rankings, ranking 11th on the overall list.
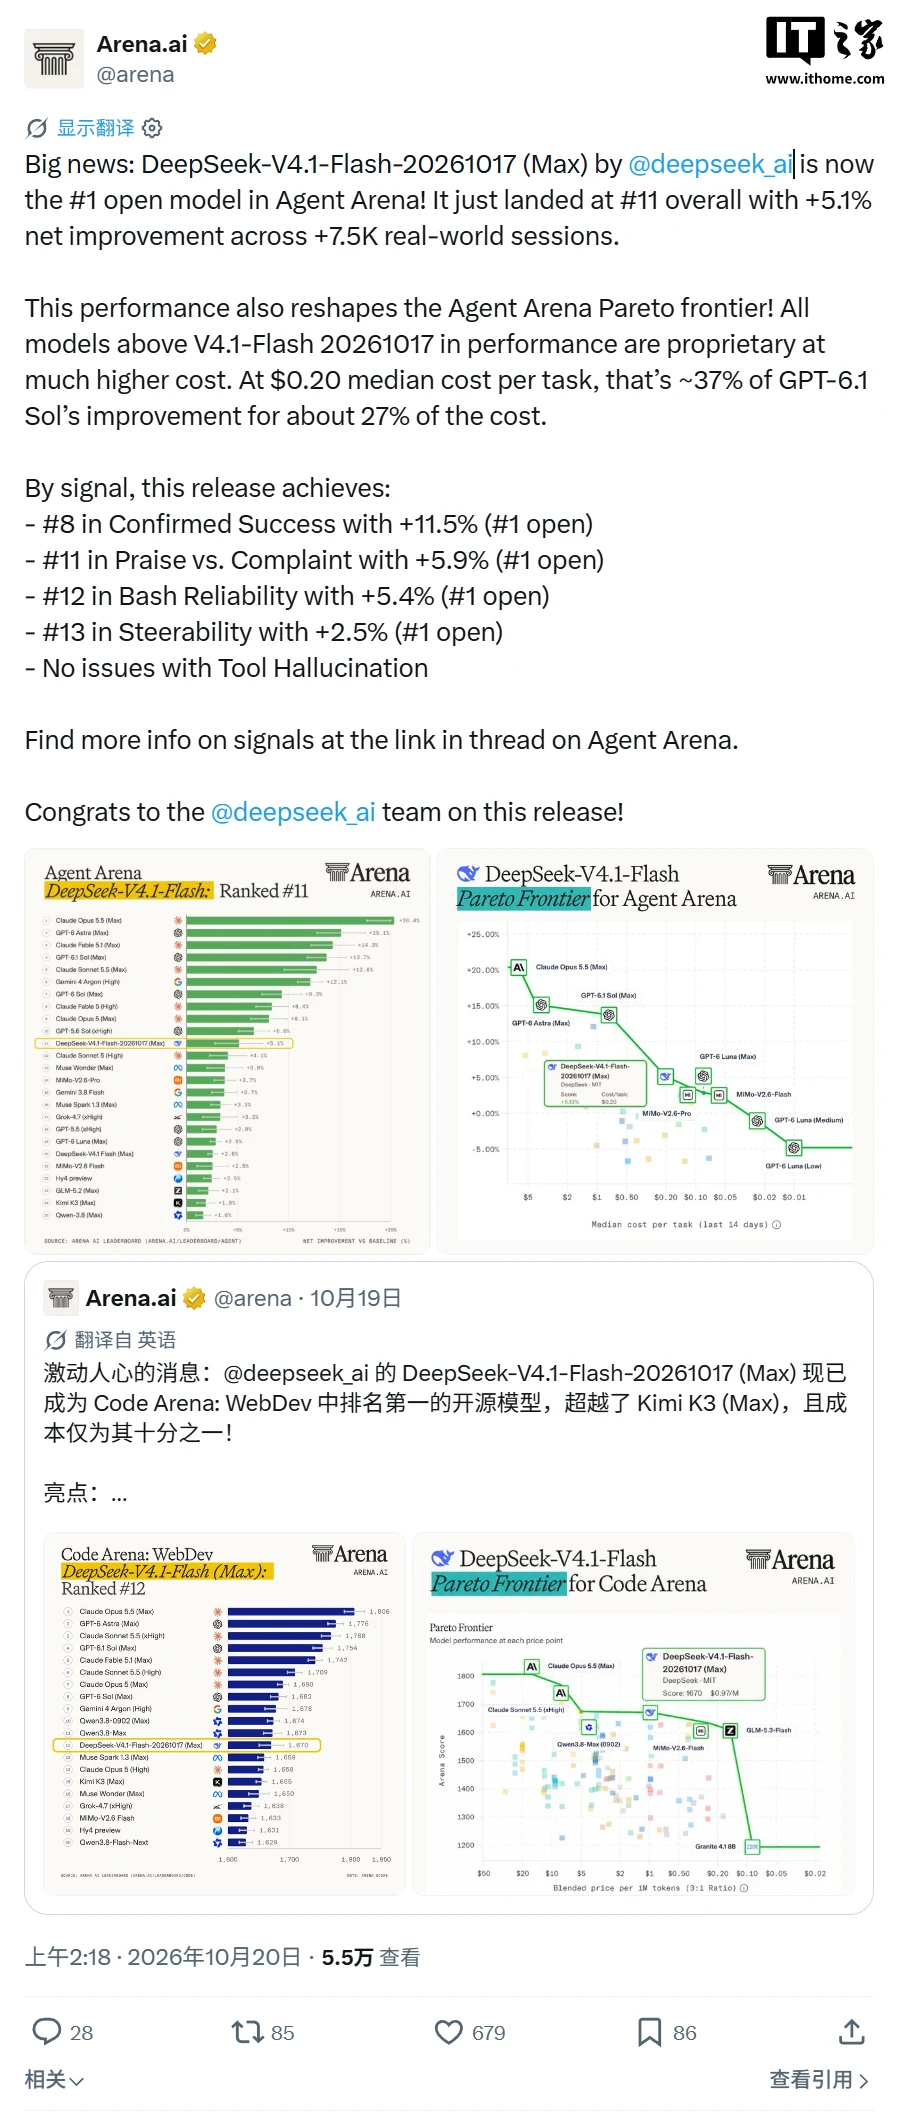
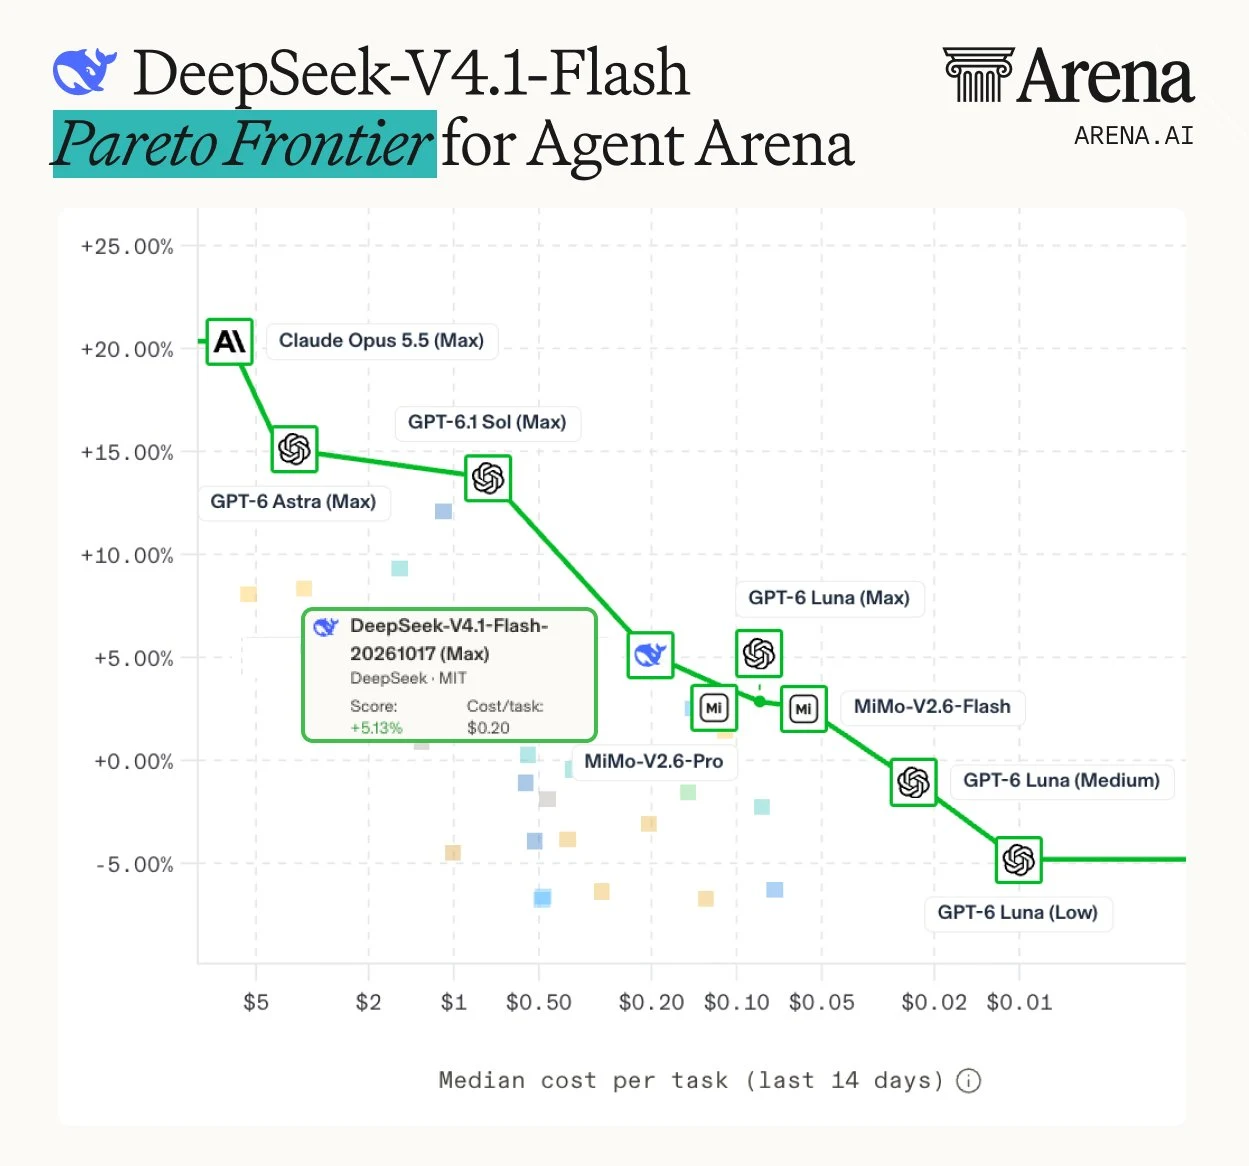
Agent Arena leaderboard shows DeepSeek-V4.1-Flash-20261017 (Max) as the first in open-source models and 11th on the overall list. According to the ranking data, this model achieved a combined net improvement metric of 5.13% based on 7498 real usage sessions, with a median cost per task of approximately $0.18 (IT Home note: equivalent to about 1.2 RMB at current exchange rate).
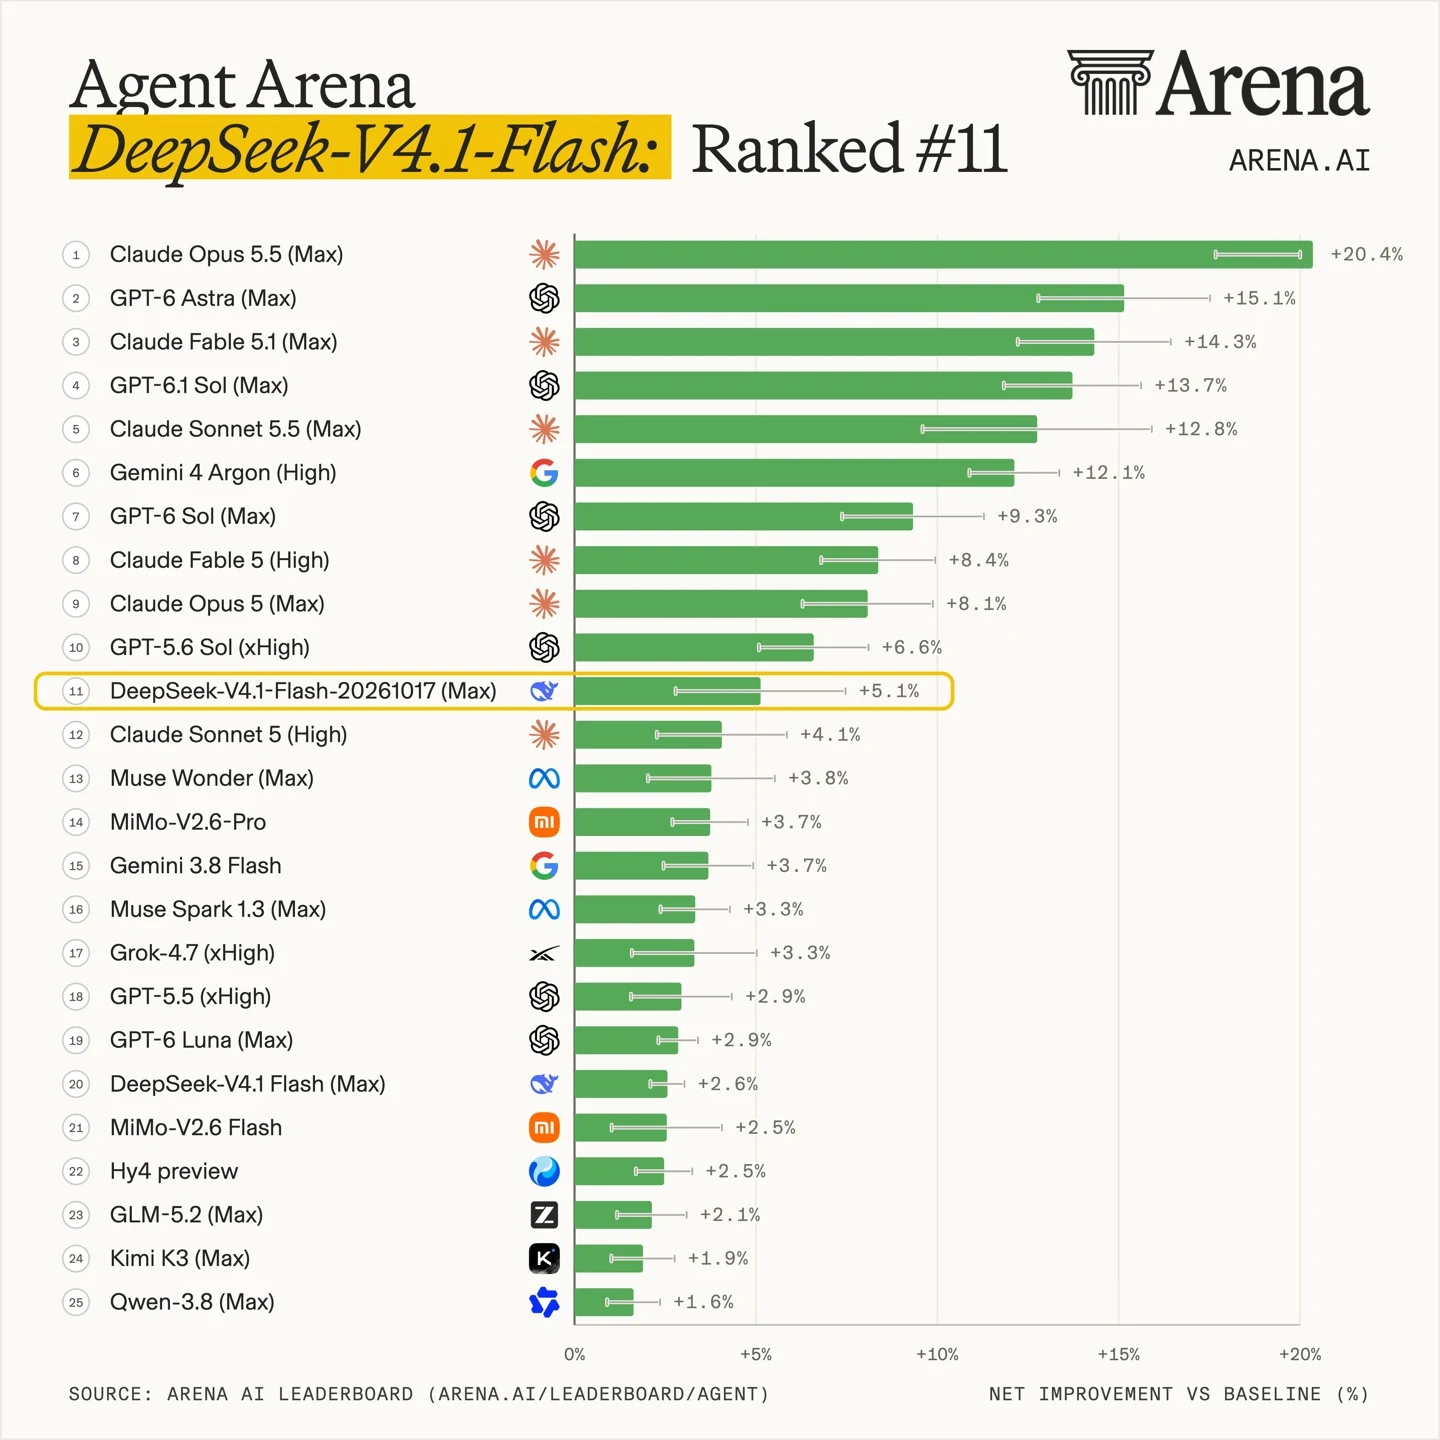
In terms of specific metrics, the model ranks first among open-source models in terms of task success confirmation, user positive and negative feedback, and Bash command execution reliability. Specifically, the task success confirmation metric is 11.54%, placing it 8th on the overall list; the user positive and negative feedback metric is 5.89%, ranking 11th; the Bash command execution reliability metric is 5.42%, placing it 12th; and the guidanceability metric is 2.46%, ranking 13th—also first among open-source models.
The Arena rankings also show that the model’s tool hallucination metric is 0.48%. This metric is used to measure situations where the model pretends to have tools it doesn’t actually possess; the lower the value, the fewer such issues there are. Based on this metric, the model ranks 7th in the rankings.
In terms of costs, the median single-task cost for DeepSeek-V4.1-Flash-20261017 (Max) is approximately $0.18 to $0.19, with slight variations based on the pages showing the different rankings.
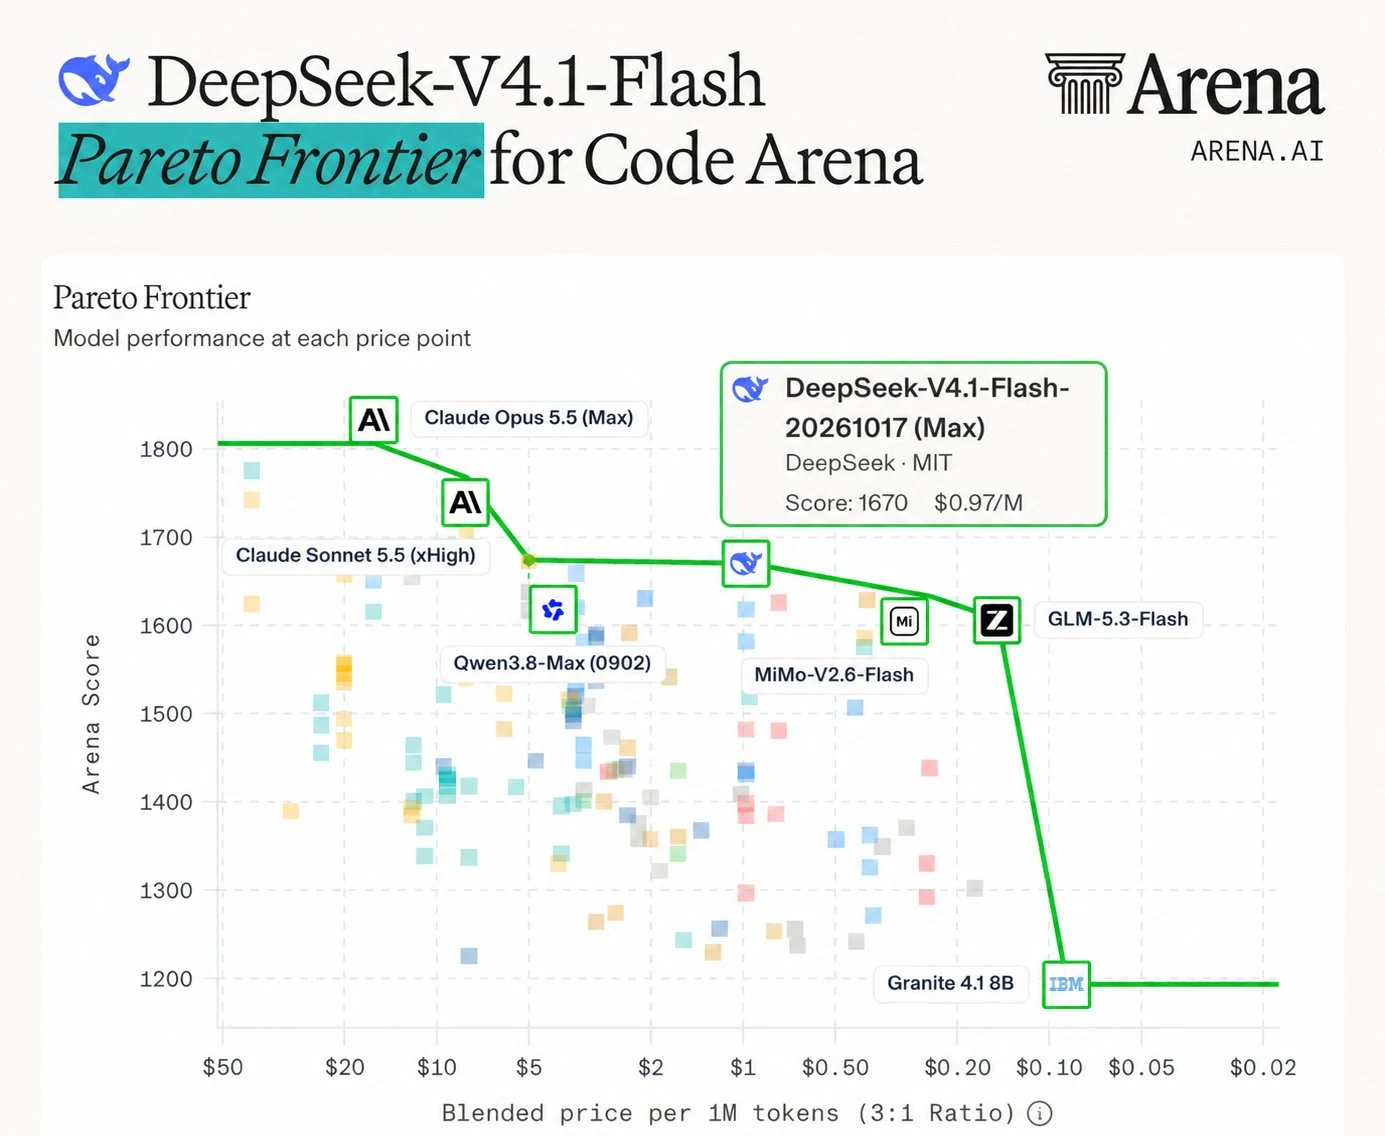
Arena also places this model at the Pareto frontier of performance and task cost, which means that under the metrics used in this evaluation, it is one of the models that cannot be surpassed by other selected models both in terms of performance and cost.
Related Reading: