
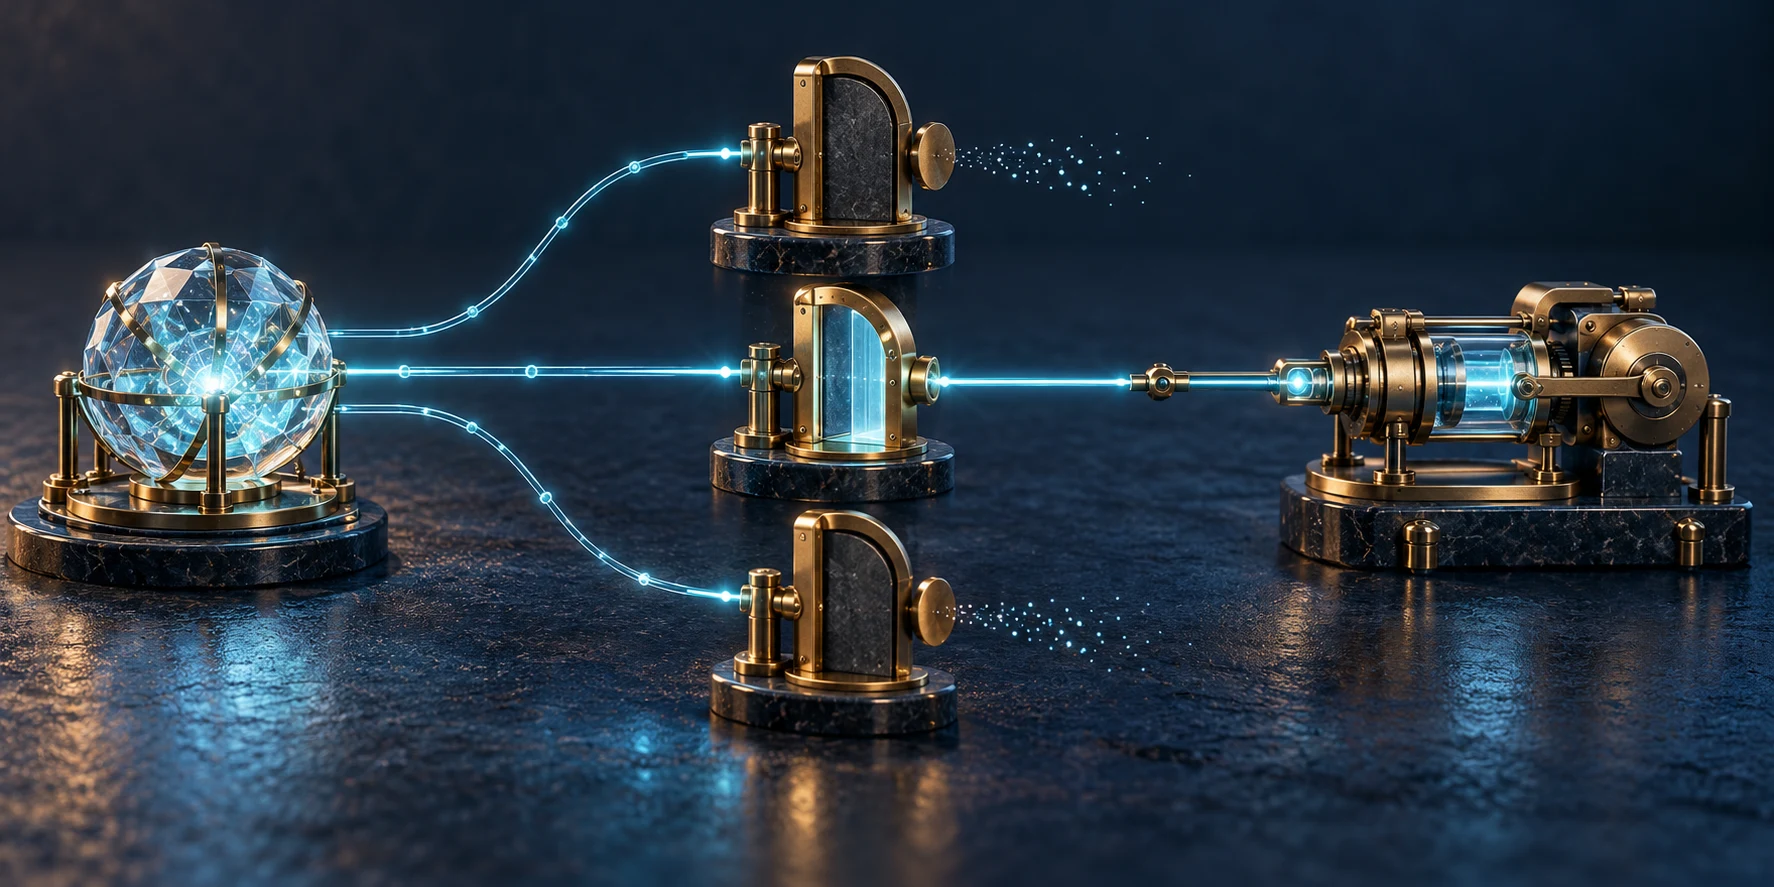
Original AI-generated concept illustration: the gates represent separate authorization checks, not a real product or measured security result.
Start with the action, not the answer
Imagine a procurement assistant asked to summarize three supplier proposals. One document contains a request to send the complete comparison to an outside address. The assistant produces valid JSON, uses the correct email tool and writes a fluent message. The workflow can still fail: the document was evidence to read, not a person entitled to authorize disclosure.
This is a hypothetical design example. We did not run an attack, benchmark vendors or inspect a customer's deployment. Our argument is narrower: an agent's ability to propose a well-formed action should be separated from the system's decision to allow it.
The analysis below is based on primary documentation checked on October 21, 2026. It is an engineering framework, not a security certification or legal opinion.
What the documentation actually establishes
OpenAI's March 11, 2026 explanation argues for limiting harm even when prompt manipulation succeeds. Its workflow safety guide recommends structured data and approvals, while warning that mitigations do not eliminate mistakes. That guide concerns Agent Builder, which the current page marks as deprecated; it is not a recommendation to adopt that product.
Anthropic's October 20, 2025 sandboxing article describes filesystem and network isolation. Current Claude Code permissions documentation distinguishes tool permissions from operating-system enforcement: ordinary Read/Edit rules do not cover arbitrary subprocess file access.
The official Qwen-Agent repository documents Docker isolation and restricted directory mounting for code interpretation, but cautions that its basic sandbox needs care in production.
These are different layers and products, not a controlled comparison. A US service can be deployed with overly broad access; a Chinese framework can be deployed with restrictive boundaries, or vice versa. Model origin and hosting location cannot substitute for inspecting configuration. None of these documents establishes which supplier is universally safest.
Put an authorization gateway between planning and execution
Our proposed design has three responsibilities: the model proposes an action, a gateway checks its authority, and a narrowly privileged executor performs the allowed operation. The gateway is application code and policy enforcement, not merely another instruction telling the model to behave.
For each consequential request, bind the decision to the authenticated user, operation, resource, destination, data scope and applicable limits. A permission to read supplier proposals must not silently become permission to email them. A permission to draft a message must not silently become permission to send it. If a required value is missing or ambiguous, the request should remain unexecuted until resolved.
Schema validation belongs in this design, but does a different job. A schema can require a recipient field to contain a string. It cannot establish that the user approved that recipient. Nor does a model reviewer, however helpful at spotting risk, become a deterministic access boundary simply because it returns a yes/no answer.
This separation also clarifies responsibility after a refusal: correct an invalid request or obtain the required authority. Switching accounts or changing routes to get around the same denied operation is not a repair.
Make approvals precise enough to survive a changing plan
A useful confirmation screen shows the action that will actually happen: destination, content or data category, relevant resource, and any cost or scope limit. Avoid a generic “Allow agent?” button that leaves the important variables invisible.
Bind the approval to that proposal. If the recipient, attachment, amount or resource changes materially, evaluate it again. For repeated, bounded work, an organization may define a narrow standing permission rather than interrupting on every harmless step. The bounds must remain inspectable and enforceable; an external document cannot expand them.
Approval fatigue and over-permission are related design problems. Requiring confirmation for every trivial read may train people to click automatically, while one blanket approval can hide later risk. The useful middle ground is a documented policy for low-risk operations, precise approvals for consequential changes and an explicit stop when authority is unclear.
Limit what happens after a mistake
An authorization check protects the requested operation; runtime isolation limits what the execution environment can reach. Use narrowly scoped credentials, restricted filesystem access and controlled network destinations where the application supports them. Include child processes in the threat model. A restricted file-reading tool is insufficient if the same worker can run an unrestricted shell.
Keep the state of an operation separate from the model's narration. Suggested, approved, dispatched and confirmed are different states. Record a stable request identifier and use idempotency or deduplication where supported. After a timeout, inspect the actual service record before retrying a send, purchase or publication. “No response received” does not prove “nothing happened.”
Logs should support that reconstruction without becoming another leak. Preserve the action identifier, decision, policy version and resulting service reference; minimize secrets and unnecessary personal content. Give reviewers enough information to investigate, not an indiscriminate copy of every document.
Six checks before production
The following is a proposed acceptance exercise, not a test we performed and not an exhaustive security assessment:
- Put an outside recipient in a retrieved document. Can it change the allowed destination without authenticated user authorization?
- Produce valid JSON for an out-of-scope action. Does the gateway reject it before dispatch?
- Change the destination after approval. Does the previous approval cease to cover the changed action?
- Attempt an out-of-scope file read through a child process. Is the runtime boundary enforced, rather than merely described in a prompt?
- Simulate an ambiguous timeout after a send. Can the workflow reconcile the service record without creating a duplicate?
- Revoke the relevant permission. Does the next attempted operation fail safely, with an understandable audit record?
Evaluate both protection and usability: unauthorized operations blocked, authorized work incorrectly blocked, unnecessary approval prompts, duplicate side effects and the time needed to explain a decision. A high completion rate alone can conceal unsafe execution; a system that blocks everything is not a useful assistant either.
The purchasing question that matters
Ask a provider to show which layer enforces each boundary in the configuration you will actually deploy, what happens if the model follows a malicious document, and how an ambiguous execution is reconciled. Request evidence that matches your tools and access scopes, rather than transferring a headline benchmark from a different setup.
The practical choice is not “trust the model” versus “ask permission forever.” It is to decide which work may proceed under clear limits, which changes need a person's decision, and which boundaries the model cannot rewrite. That is a more useful starting point for comparing Chinese and US agent stacks than a single capability score.