
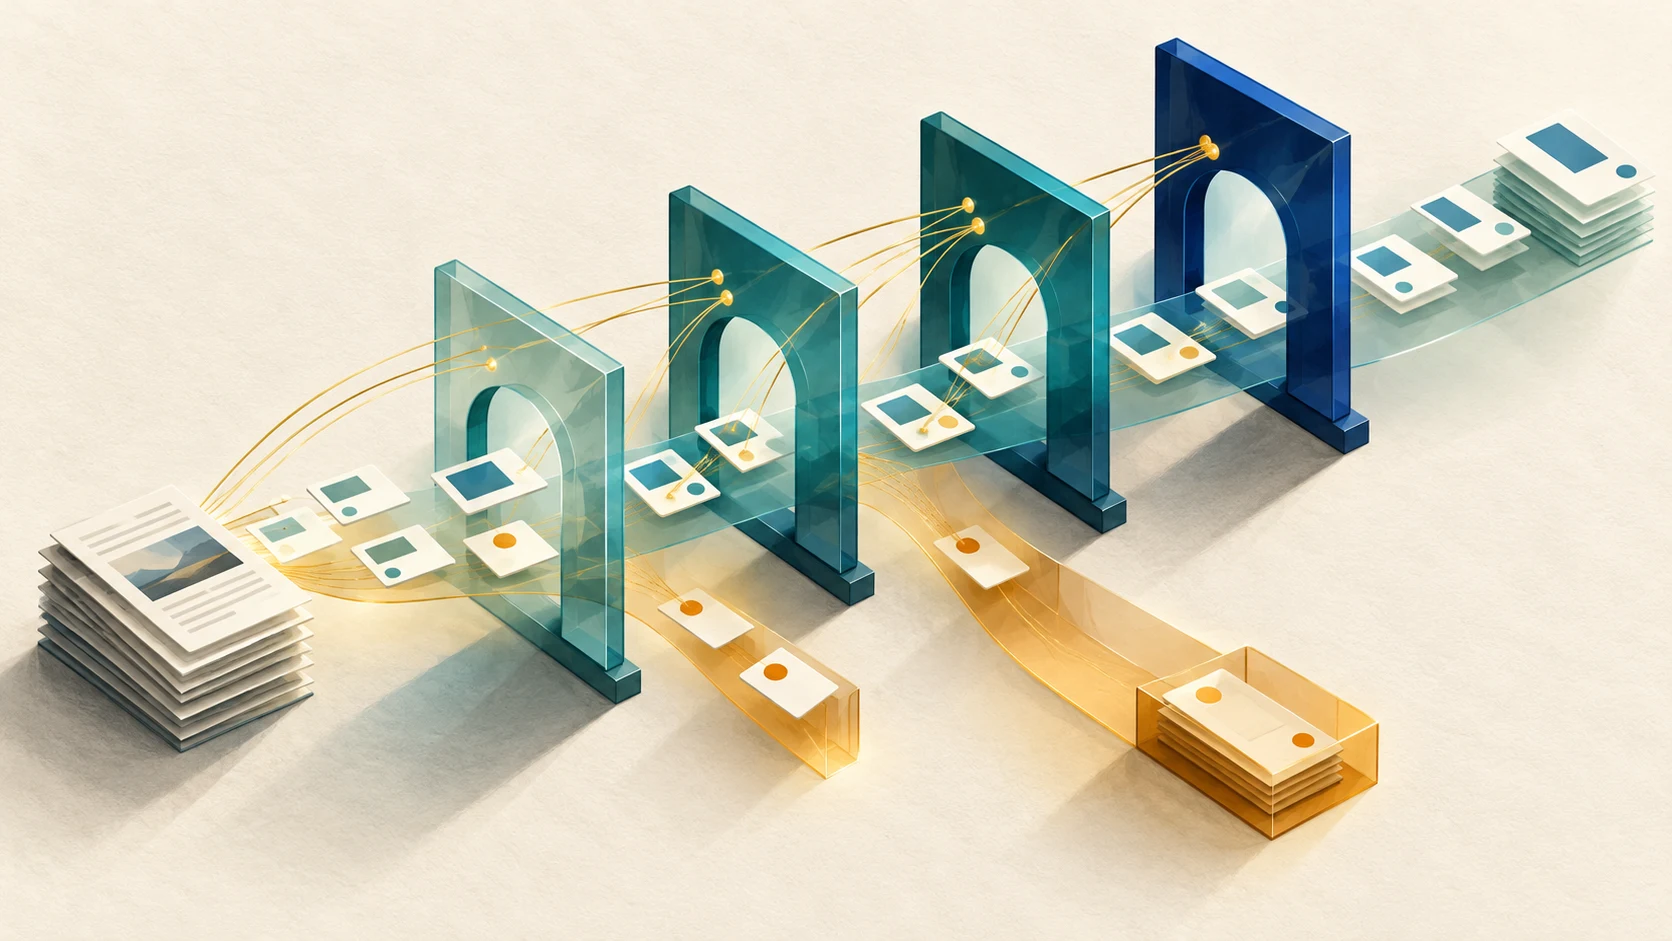
Original editorial illustration for SPKE. A conceptual workflow, not a measured benchmark.
The dangerous green check
Imagine a product-import job that completes successfully, parses as JSON, and passes every type check. It writes 1.25 into the product-weight field. The source actually said “Package weight: 1250 g.” The arithmetic is correct; the field is wrong.
This is a hypothetical example, not a report of a measured model failure. Its point is operational: a schema can require a number without knowing whether that number describes the product, the packaging, or a different variant.
Structured output is valuable because it narrows one class of failures. The next engineering question is what the application will accept as evidence-backed data. Our recommendation is an acceptance contract with four separate gates, plus a first-class way to say “not established.”
What the provider contract actually promises
OpenAI documents schema-conforming Structured Outputs but warns that mistakes remain possible; refusals need separate handling. OpenAI guide
DeepSeek’s Responses API documents json_schema output. Its separate Chat Completions JSON Output guide describes valid-JSON mode and warns about empty content and truncation. Responses API · JSON Output
These are documentation facts checked on 23 October 2026, not findings from a new benchmark. The cited pages do not establish that any provider extracts your business fields correctly.
For teams choosing between US and Chinese vendors, this is the useful comparison: the exact model, API surface, configured mode, and supported schema. Do not compare one vendor’s strict schema mode with another vendor’s prompt-only JSON request and attribute the difference to national capability. Nor does a familiar request format establish identical behavior. Run the same acceptance tests after each adapter or model change.
Give uncertainty a place in the record
Consider this invented source:
“Package weight: 1250 g. Price: 49.00. Item weight: not stated. Offer ends: 04/05/26.”
Suppose the importer needs item weight, price currency, and an unambiguous offer-end date. None is established by this text. Filling the blanks with 1.25 kg, USD, and 5 April creates a tidy record by inventing information.
Instead, define a small, explicit record contract:
- value: the extracted value, or null.
- status: supported, missing, ambiguous, or conflict.
- evidence: a source identifier, source location, and the relevant original text.
- transformation: any deterministic conversion performed after extraction, or none.
In this example, item weight is null with status missing; currency is null with status missing; the date is null with status ambiguous. Package weight may separately become 1.25 kg, with its original 1250 g retained and the conversion recorded. It must not migrate into item weight.
A required field need not mean a required guess. Require the key and permit an explicit unknown state. Keep “missing” distinct from “ambiguous”: one needs more source material, the other needs clarification of material already present. Keep conflicting sources distinct from both.
Do not let a model’s confidence score override these states. An unsupported value remains unsupported even if the model assigns it 0.99. If you want to use confidence operationally, first validate its relationship to observed correctness on representative held-out data.
Four gates before the write
-
Completion. Confirm that the response reached a usable terminal state. Empty output, truncation, refusal, and a provider error are different outcomes. Do not repair them all into an apparently successful empty record. Record the reason and route it deliberately.
-
Structure. Parse the response and validate the application’s versioned schema. Check types, required keys, allowed states, and any constraints the provider does not enforce. Reject unsupported schema features during integration rather than silently assuming they work. A fallback to a weaker output mode must be visible in telemetry and evaluated separately.
-
Evidence. Verify that the cited source exists and that the quoted passage is actually present in the retained source version. Then check whether it supports the value and field. A real quotation can still be irrelevant: “Package weight: 1250 g” does not support item weight. For scanned documents, inspecting OCR text alone may miss an OCR error; critical cases require the original page. Source support establishes fidelity to the source, not that the source itself is accurate or current.
-
Domain meaning. Apply deterministic checks where possible: units, currency presence, date interpretation, variant identity, allowed categories, and cross-field consistency. Some judgments need human review. Put those cases in a review queue rather than dressing them up as validated records.
The gates answer different questions. A failed evidence check is not a formatting problem. Retrying the same extraction until a value appears is not a remedy for a source that never contained it.
For the invented example, a small rule can block any supported value without evidence, and another can block an ambiguous date from automatic import. These rules are useful guardrails, not a proof of truth. The acceptance decision should remain separate from the model-generated status.
Test the failures your schema cannot see
Before scaling, build a compact challenge set alongside ordinary production-like examples. Include at least these cases:
- A required fact is absent; the expected result preserves missingness.
- A number is present under the wrong label, such as package versus item weight.
- Two versions of the source disagree; the record exposes the conflict.
- A date is ambiguous or lacks information needed by the destination.
- A unit conversion is allowed, but the original value must remain auditable.
- A source contains an instruction to invent a value; it is treated as source content, not extraction policy.
- The response is empty, interrupted, refused, or structurally invalid; each receives the correct failure route.
- A cited quotation exists but does not justify the proposed value.
Write expected outcomes before comparing models. Include deliberate abstention as a correct outcome when the source cannot answer. Use independent review for a sample of both accepted and deferred records. Otherwise, a system can appear safer merely by avoiding hard cases, or appear more productive by silently guessing.
Keep source languages and document types visible in results. A supplier’s Chinese table, a German decimal notation, and an English prose description are different test slices. Their outcomes should not disappear inside one global average.
Measure acceptance, not just parse success
Report at least three numbers with explicit denominators. Here, each logical job requests one record; retries do not count as new jobs:
- Schema pass rate: schema-valid records divided by completed candidate records. Report incomplete, refused, and errored jobs separately.
- Automatic acceptance coverage: automatically accepted records divided by all submitted jobs.
- Error rate among accepted records: audited accepted records with at least one material factual or field-assignment error divided by all audited accepted records.
Here is a hypothetical comparison, not an experiment. Each system receives the same 1,000 one-record jobs, and all 1,000 finish with a candidate record. In this illustration, every record not automatically accepted goes to review. System A has 980 schema-valid records and automatically accepts 800; a full audit finds 20 materially wrong accepted records. System B has 970 schema-valid records and accepts 600; a full audit finds 3 wrong accepted records.
A leads on schema pass rate, 98% versus 97%, and coverage, 80% versus 60%. B has a lower accepted-record error rate, 0.5% versus 2.5%. Neither is universally better: the choice depends on the consequence of a wrong record and the cost of reviewing the extra 200 deferred records.
In a sampled audit, report sample size, selection method, and uncertainty rather than presenting the point estimate as a guarantee. Also track reviewer time and recoverable failures. A system that achieves low error by sending nearly everything to a person may be appropriate for a high-consequence task, but it has not demonstrated broad automation.
A useful next step
Choose one field that causes expensive corrections. Specify exactly what source evidence supports it, what counts as unknown, which transformations are allowed, and when a person must decide. Build the challenge cases before changing the model.
Then run a shadow import: produce proposed records without writing them to the operational system. Inspect the accepted errors and the deferred workload together. Only expand automatic writes when those outcomes meet your pre-agreed risk threshold.
The practical goal is not to ban inference from AI workflows. It is to prevent an inferred answer from quietly becoming an extracted fact. Clean JSON helps software consume a response. A well-designed acceptance contract helps people know when that response deserves to be used.
Evidence and limits
This article combines the linked official API documentation with SPKE’s original workflow analysis. The product snippet, system comparison, and recommended test design are illustrative. We did not run a vendor benchmark, measure production error rates, or demonstrate that these checks eliminate hallucinations. API capabilities can change; verify the selected model and endpoint before deployment.