Artificial Analysis · X更新于

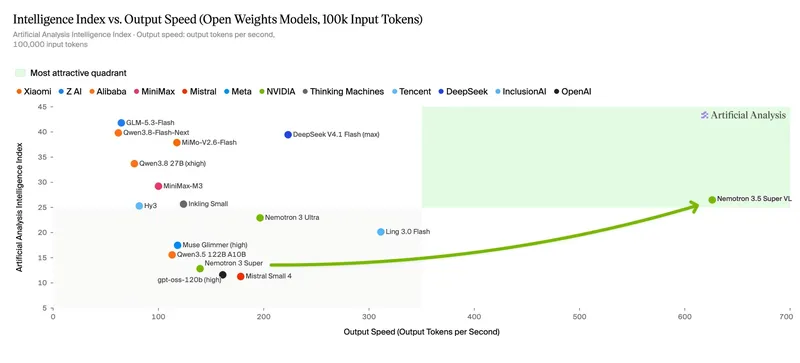
在提供 NVFP4 权重的预发布 @DeepInfra 端点上测得,Nemotron 3.5 Super VL 的输出速度可达约 630 tokens/s,并…

Artificial Analysis在DeepInfra预发布端点(使用NVFP4权重)实测Nemotron 3.5 Super VL在100k-token提示下输出约~630 tokens/s,为其测得智力指数20分以上模型中最快;此为预发布端点的第三方测量数据。

配图来源 · Artificial Analysis · X

在提供 NVFP4 权重的预发布 @DeepInfra 端点上测得,Nemotron 3.5 Super VL 在 100k token 提示词下的输出速度可达约 630 tokens/s。这是我们在该提示词长度下测得的所有在 Intelligence Index 上得分达到 20 或以上的模型中最快的

这约为 Inkling Small(124 tokens/s)的 5 倍、Nemotron 3 Ultra(235)的 2.7 倍,以及 Nemotron 3 Super(140)的 4.5 倍。它的首个 token 返回时间为 1.8 秒,而 Nemotron 3 Ultra 为 4.4 秒,Inkling Small 为 8.5 秒
原始出处

Artificial Analysis · X

内容说明

原始发布及相关权利归来源方。

机器翻译 · 请以原文为准