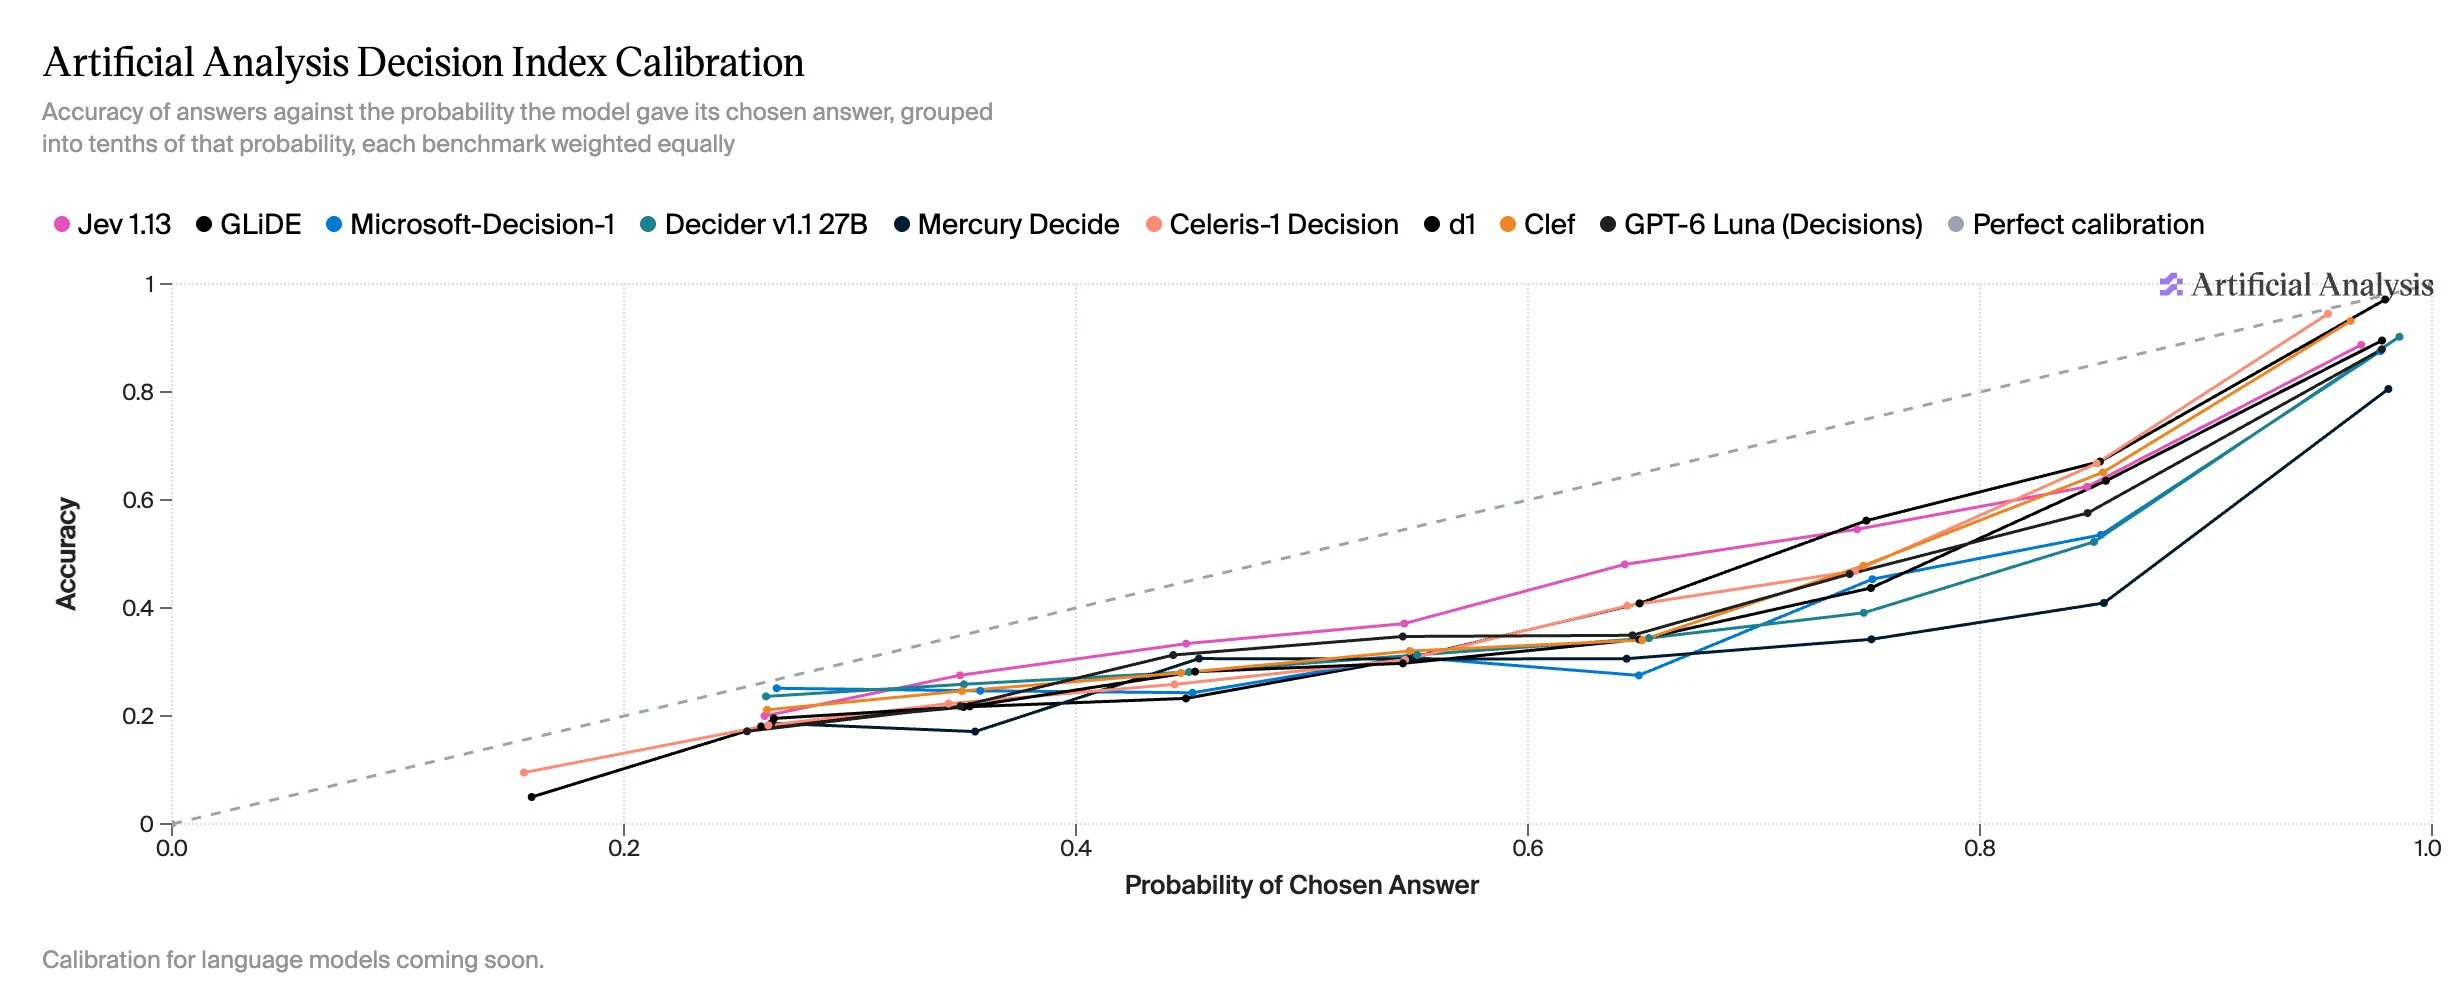
Decision models are poorly calibrated on knowledge and reasoning tasks. Across almost all probability levels for chosen answers, accuracy falls below that probability for all decision models. This gap is largest on AA-Omniscience-Decision and HLE-MultiChoice, while most models are relatively well-calibrated on WildGuardTest (classification) and When2Call (tool calling)