
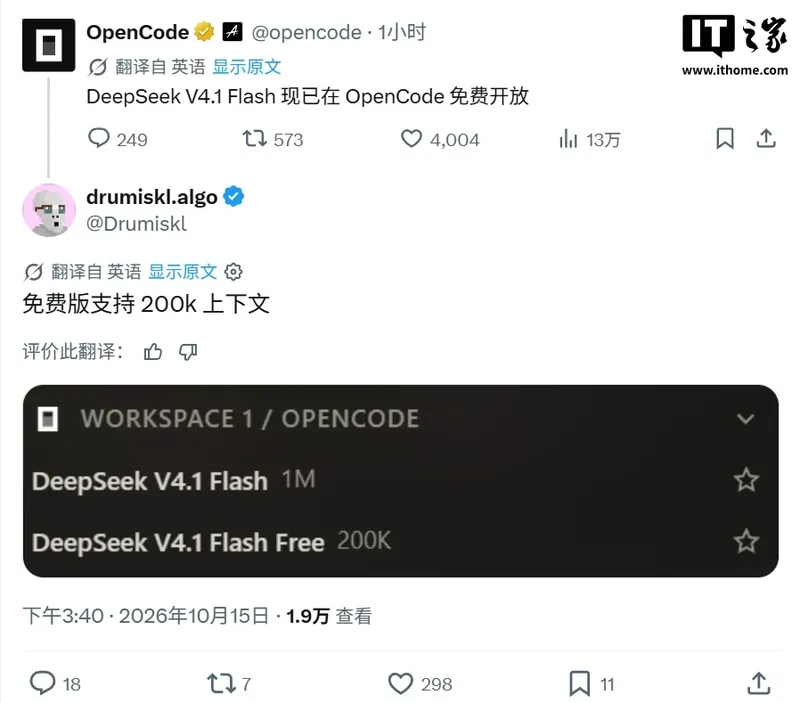
IT Home On October 15, OpenCode announced that DeepSeek V4.1 Flash is now available for free. The free version supports a 200K context window, which is lower compared to the 1M context version.
This free access is a further step based on the “Operation Cheepseek” program that was established earlier. In September this year, OpenCode temporarily increased the usage quota of DeepSeek V4.1 Flash in the OpenCode Go package from $15 to $60, and then adjusted it to $80 on October 12. After this free access, the invocation of this model within the OpenCode platform will no longer be counted toward the quota consumption.
DeepSeek V4.1 Flash was officially released on September 10, 2026. It is a native multi-modal MoE model with a backbone parameter size of 552B and 196B Engram conditional memory parameters. IT Home noticed that its architecture uses a causal encoder-decoder design, where the first 20 layers of the 40-layer language backbone are causal encoders and the last 20 layers are decoders, resulting in nearly half the Prefill computational cost. There is no free API tier on the DeepSeek official platform, and billing is done using a prepaid pay-as-you-go model.
In terms of user feedback, the generation speed (TPS) is the focus of community discussions. Many users reported significant fluctuations in speed. Some users mentioned that on the ollama cloud platform, the output speed reached up to approximately 490 tokens/s, but it was overall unstable, with the lowest speeds dropping to fifty to sixty tokens/s during the midday to afternoon period.
In the OpenCode Go package, some users have reported that the TPS drops below 100. Additionally, community tests show that performance decreases as the context size increases. Some users report that when the context exceeds 100K, the TPS drops below 100, and at 200K, it is approximately 50 tokens/s.
Related Reading: