
October 16, Beijing– Fanshi Intelligence Technology Group Co., Ltd. ("Fanshi" or the "Group", stock code: 6682.HK), together with Beijing Ruisi Zhilian Technology Co., Ltd. ("Ruisi Zhilian"), announced the official launch of the one-stop production-grade AI deployment platform "ModelSphere". The platform is free and open source for enterprise users, integrating computing power management, model deployment, and runtime optimization into a unified platform, helping enterprises lower the barriers to deployment and operations and more efficiently turn computing power into secure, stable AI services usable in real business. The platform is already open-sourced on GitHub.
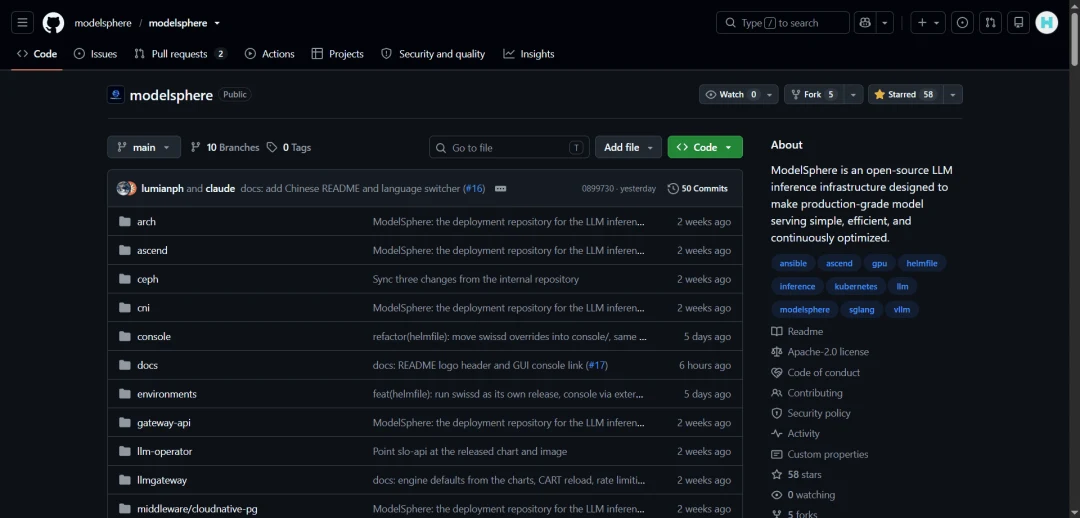
GitHub address: https://github.com/modelsphere/modelsphere
As large models enter the stage of large-scale commercialization, enterprises commonly face problems such as low resource utilization, fragmented chip ecosystems, high deployment barriers, and difficulties in production environment tuning when it comes to computing power coordination, model deployment, and efficiency optimization. ModelSphere is committed to integrating these tasks into a unified deployment and management process, reducing enterprises' repeated investment in underlying system adaptation, resource scheduling, and daily operations, so that enterprises can embed various open-source large models into core business processes without deeply mastering complex work such as driver compilation and hardware adaptation, allowing technical teams to focus more on application development and business needs.
ModelSphere has four core advantages:
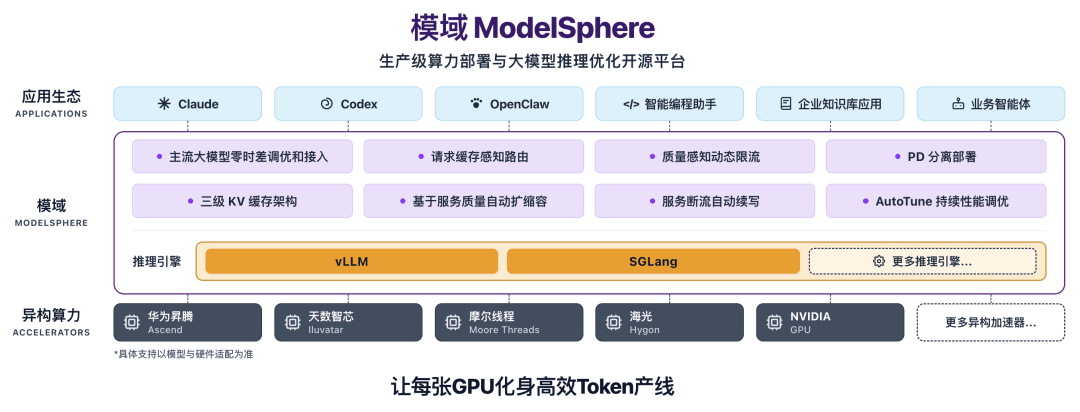
1. Simplified deployment to ensure stable operation of model services:ModelSphere provides a graphical operation panel and pre-built deployment capabilities, reducing the writing of environment configuration code, helping developers quickly build inference services for large models and simplifying [deployment on] different chip clusters. The platform has built-in enterprise-grade capabilities such as automatic elastic scaling, PD-disaggregated deployment, three-level KV cache, high-availability load balancing, and automatic resumption of interrupted service streams, supporting stable operation of model services in production environments.
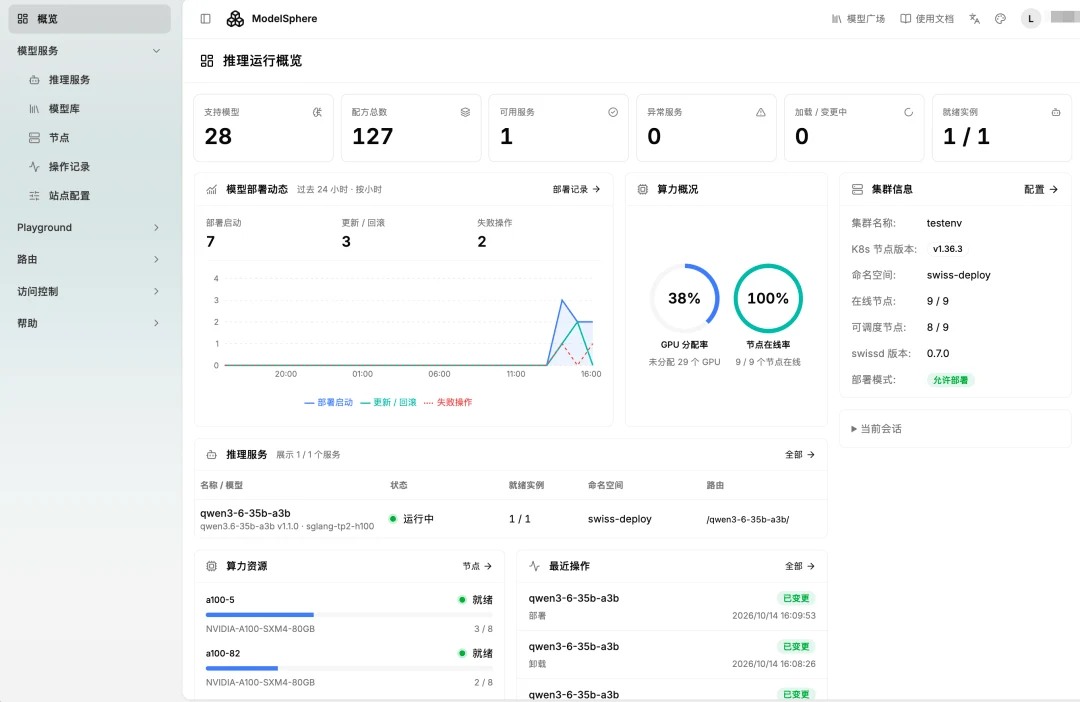
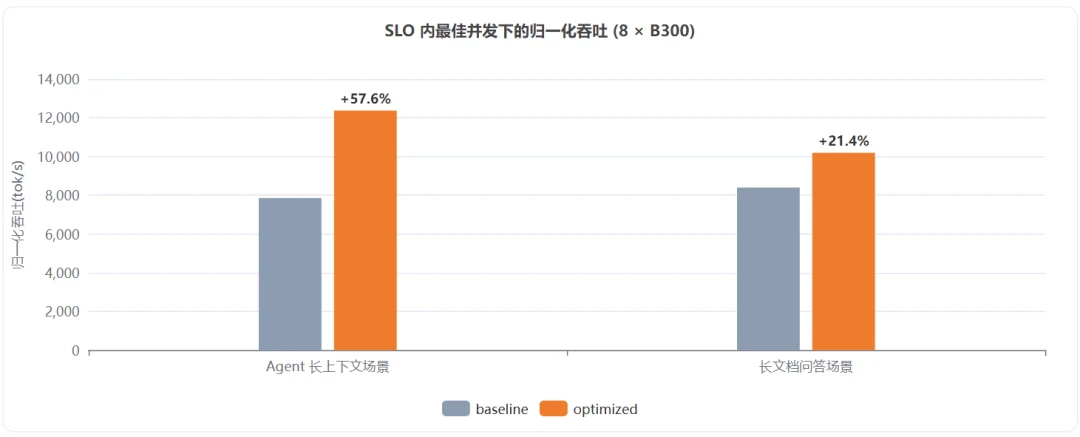
2. Continuous automated tuning to improve model operating efficiency:The platform has built-in AutoTune intelligent model scheduling strategies, as well as adaptive load-balancing scheduling combined with hardware acceleration capabilities, optimizing the model's ability to process requests and first-response speed. The system's limit throughput efficiency is significantly improved by approximately 285% over the baseline, with performance leaping to 4 times the original, truly achieving the "full-blooded" release of computing power.
3. Unified management of multiple chips, reducing redundant adaptation:The platform integrates the EngineX inference engine, supports and performs deep tuning for a variety of computing chips, and can uniformly and hybridly schedule domestic computing resources such as Huawei Ascend, Iluvatar CoreX, Moore Threads, and Hygon DCU, so users do not need to rewrite underlying logic code for different chips.
4. Continuous optimization and adaptation of mainstream models to accelerate deployment and application:The ModelSphere team continuously follows open-source community iterations and has adapted and optimized mainstream models such as DeepSeek-V4/V4-Flash, Qwen, Kimi, MiniMax, and GLM, supporting rapid deployment after model release with performance tuning for production environments, helping enterprises put new models into actual business.
On the technical level, ModelSphere works in coordination with inference engines such as vLLM and SGLang: the inference engines are responsible for improving the computing efficiency of a single server, while ModelSphere is responsible for cluster architecture-level management and optimization, including load- and cache-aware request routing, a unified KV cache pool, quality-of-service-based automatic scaling, automatic resumption of interrupted service streams, automated performance tuning based on online data, runtime monitoring, and service management, ensuring high performance and high availability of the system in production environments.
ModelSphere is fully open-sourced under the permissive Apache 2.0 license, opening the engineering capabilities of large model deployment and optimization to more enterprises and developers, while gathering industry forces to continuously improve support for different chips and models, reduce hardware adaptation obstacles, lower the barriers to large model application, help enterprises make good use of existing computing power, and efficiently unleash the commercial potential of heterogeneous computing power.
This article was provided by Fanshi and reprinted by QbitAI with authorization; the views belong to the original author.