
Yi Shui Lu Yu, from Ao Fei Si
Quantum Bit | Public Account QbitAI
That’s right, everything is aligned.
In the past two days, DeepSeek “fell first and compensated later”, so some people guessed that Teacher D might take new actions?
The result really got everyone waiting—New model DeepSeek-V4.1-Flash-1017, ready to be served quickly.
After replacing the new model, the DeepSeek Harness new version 0.2.1 has also been enhanced, as stated by the official team:
During the training of the new model, special optimizations were applied to DeepSeek Harness. This leads to improved task performance, while also reducing task execution time, minimizing output consumption, and lowering token costs.
Damn, it works faster, saves more effort, and is even more powerful!!
Also during the long weekend, Teacher D also casually offered some benefits:
Users who meet the criteria log in to DeepSeek Harness for the first time can directly receive a 6-yuan bonus, without any recharge, and it is valid for 7 days after arrival.
Note: The quota is limited and available only until it’s gone (uhuh, I have something urgent to handle~).
More powerful performance, and actually less cost
After completing the login, then look at the highlights of this model (if you remember logging into Harness before, exit first before logging in again).
The official web page, APP, and API models have now been synchronized to the new model.
Compared to the previous V4.1 Flash version, version 1017 has almost consistent improvements in all benchmark tests, with significant enhancements in code, Agent tasks, and other capabilities.
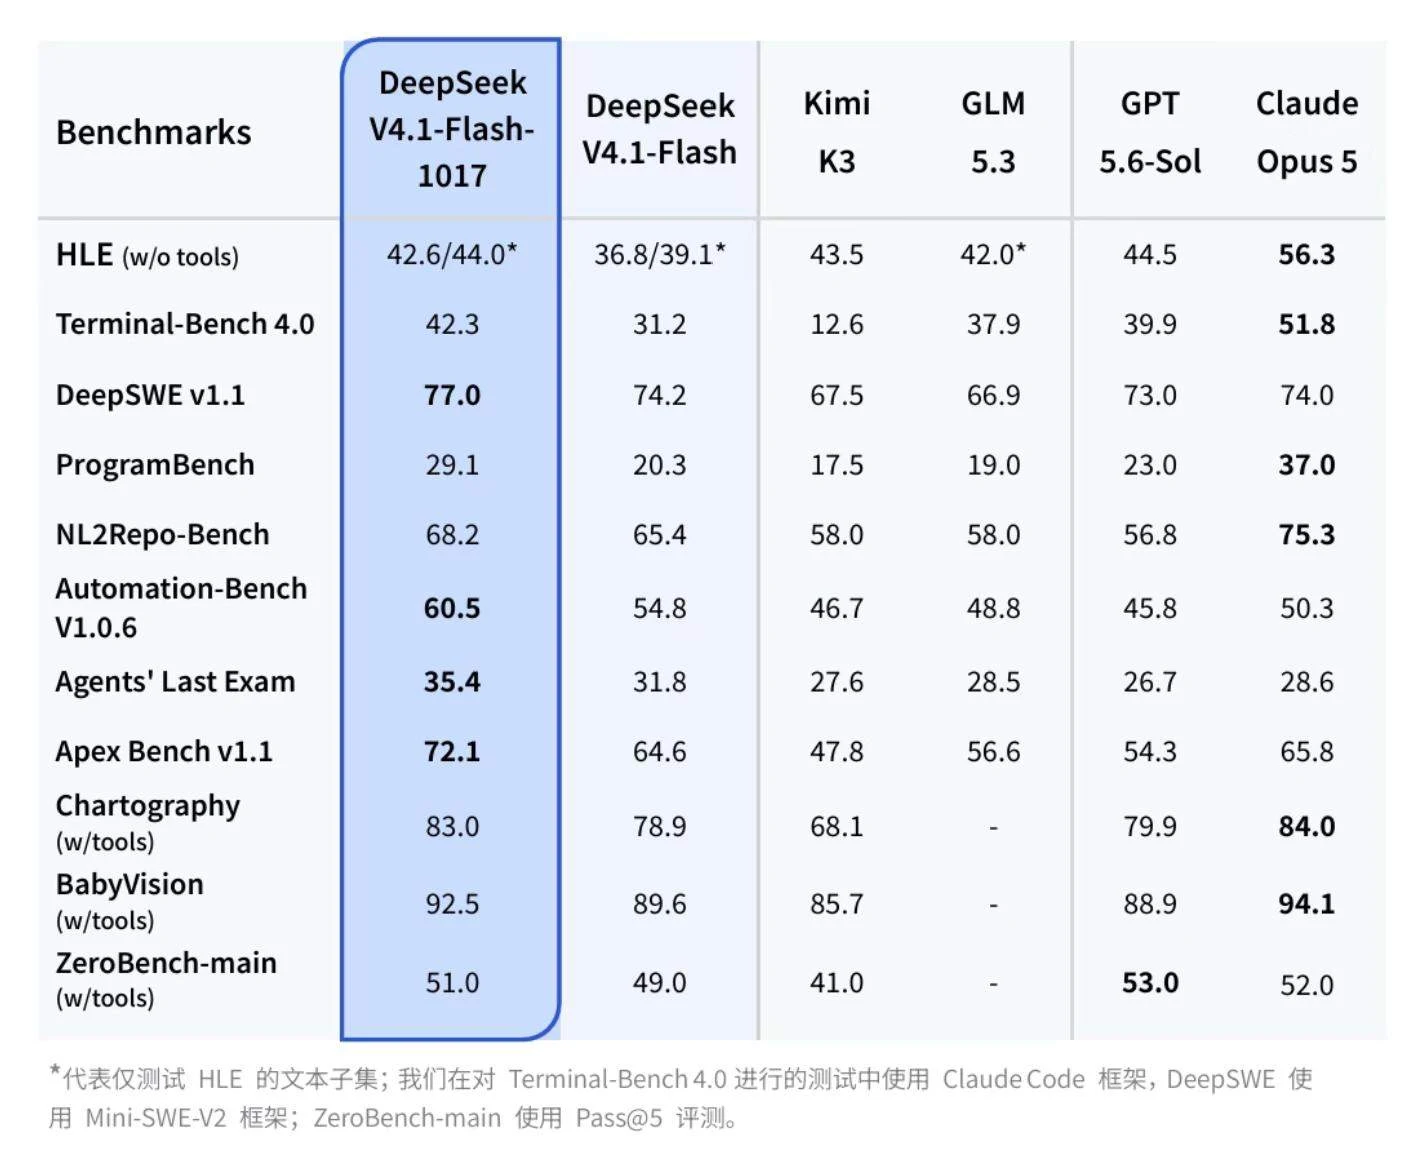
But just getting more points isn’t the most significant aspect of this update.
Because while the model’s performance improves, the task runtime and output length are instead reduced.
Hmm? It’s like making the horse run, but not giving it enough grass, right??
The official term for this is “Performance–Cost Pareto Improvement”. In the past, to make the Agent perform better, it was usually necessary to accept that it would take longer, walk a few more steps, and produce more Tokens.
At V4.1-Flash-1017, the model starts trying to take fewer detours and say less nonsense, aiming directly to complete the task.
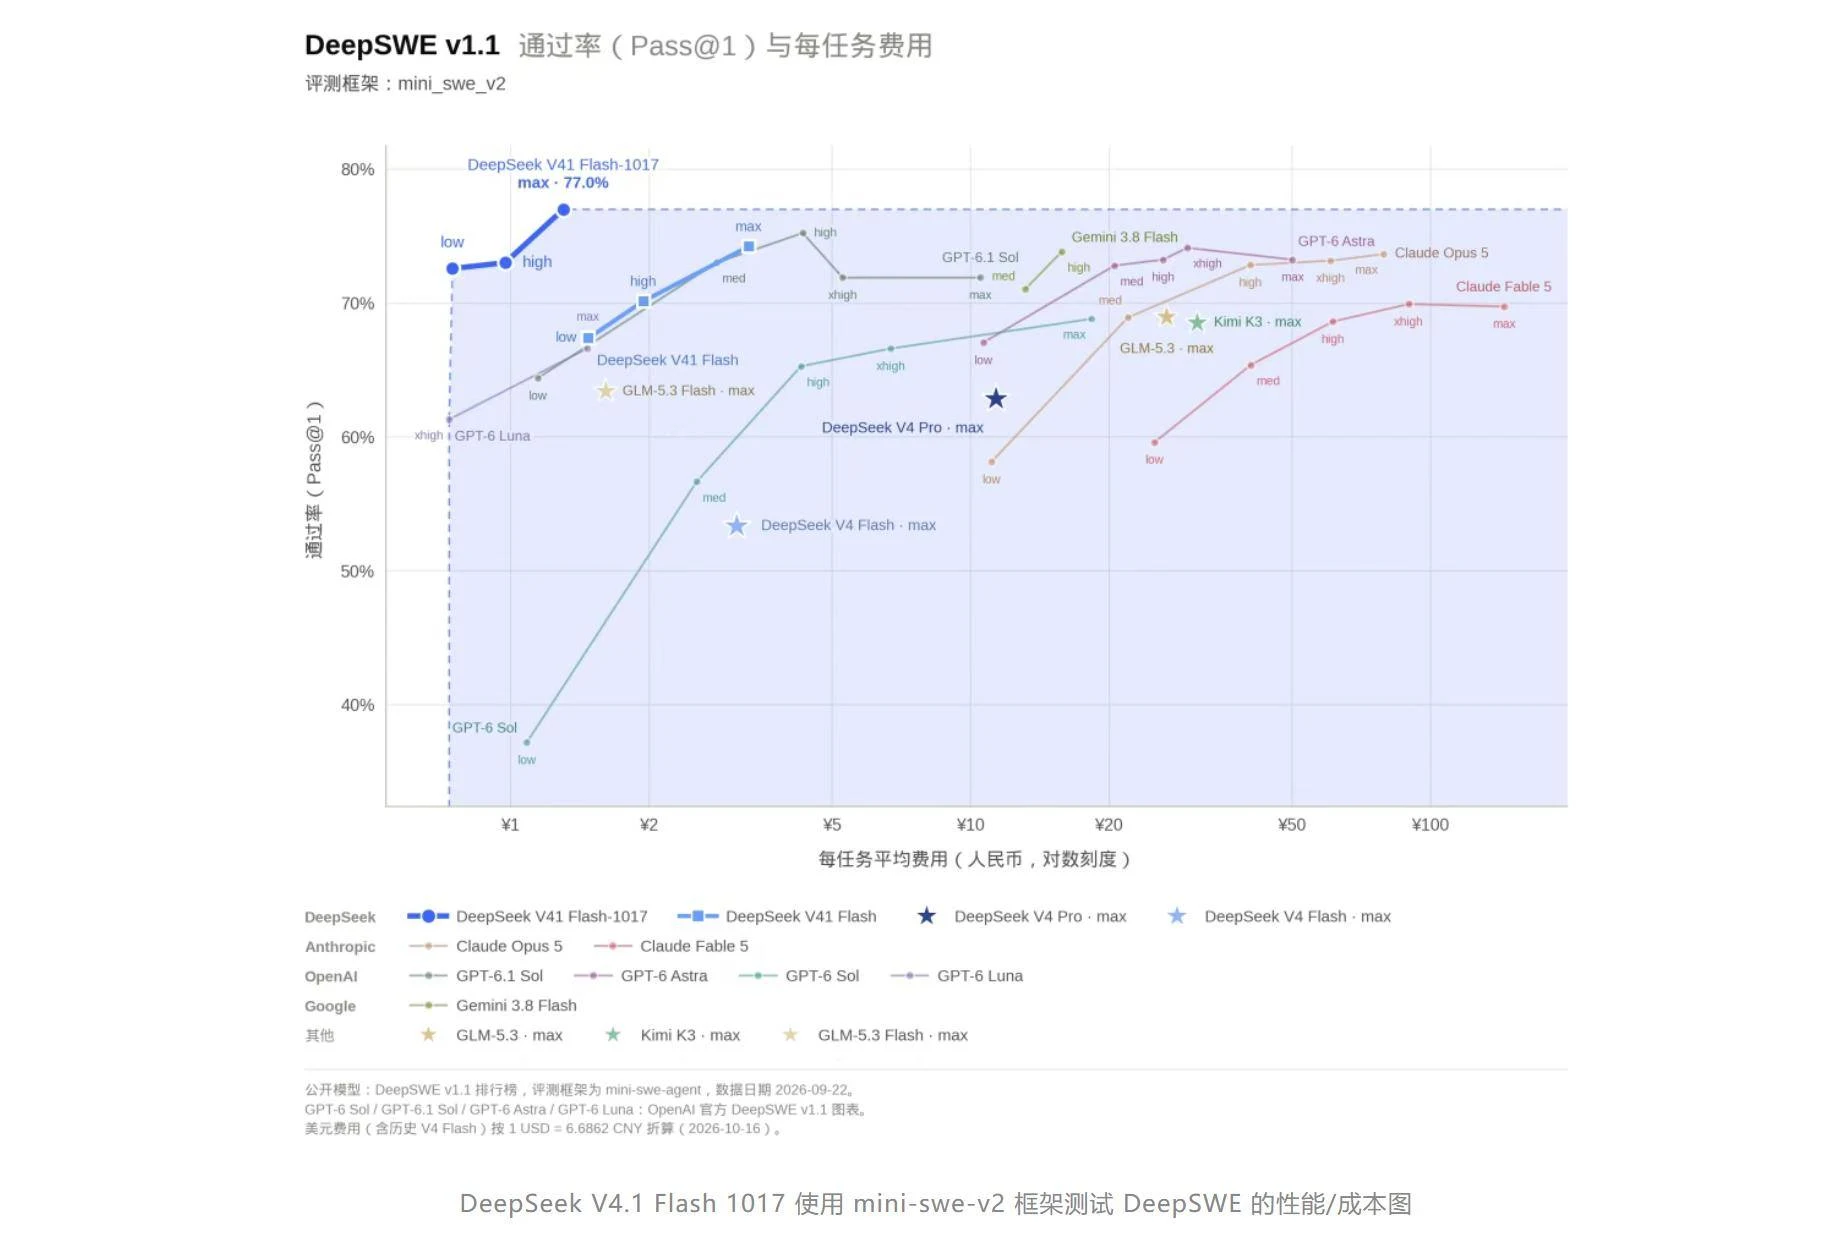
According to the DeepSWE test released by the official team, V4.1-Flash-1017 has further pushed the boundary between performance and cost across multiple Agent frameworks.
In particular, DeepSeek Harness, Tencent CodeBuddy, and WorkBuddy have all received special optimization.
To fully integrate this new capability currently, DeepSeek Harness must be upgraded to version 0.2.1-rc.1 or later.
“Wish-like Programming: One Click to Realize”
Of course, no matter how nice the benchmark tests are, it’s better to see directly what they can produce.
And the new task that DeepSeek has prepared for V4.1-Flash-1017 this time, its name is also very understandable to netizens—
"Wishful Programming".
What is the wish-granting method?
In the past, to create a complete project, you had to first explain the features, structure, interaction, and technology stack one by one to the model.
Now, the user just needs to clearly state what they want. The rest—planning, writing code, running, checking, and modifying—is handled by the model itself.
The key behind it is a set of reinforcement learning training techniques based on self-feedback.
I won’t leave work right after finishing the first version of the model. It will continue to check what I’ve created, and if anything is wrong, I’ll go back and fix it.
What is the result of this method?
The official immediately set up a huge project, essentially turning the Forbidden City into nothing.
Teacher D directly used code to create a 3D scene that can be viewed in real time and with different perspectives.
Pretty good. While others are still working on Todo List with Vibe Coding, Teacher D has already started restoring the Forbidden City with Vibe...
And each one after that is even more absurd:
The web version of the racing game starts running directly, while the Godot version of Portal 2 offers true interactivity. There’s also a dynamic 3D world that spans from prehistory to modern times.
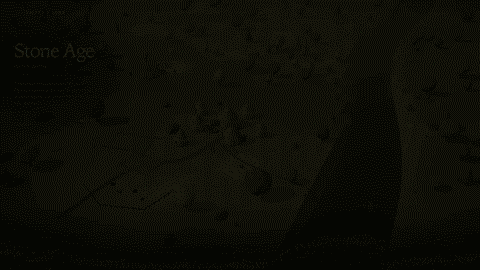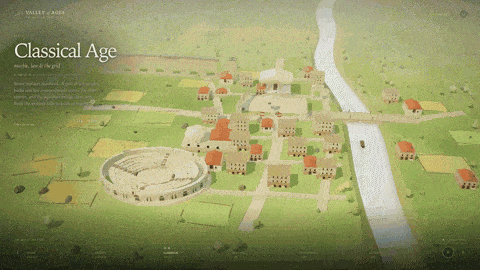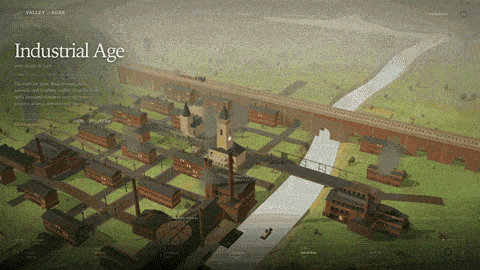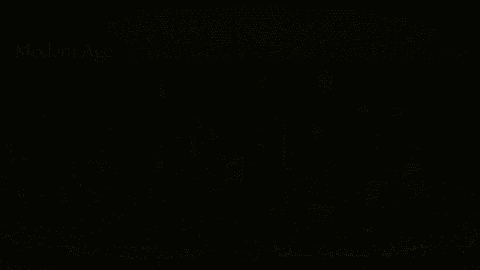
From a single sentence to a complete project that can be seen, acted upon, and played with.
“Wishful programming,” this time it really made Teacher D succeed.
The model was suspected of being leaked before its release; “more intelligent, and also more concise.”
In fact, DeepSeek-V4.1-Flash-1017 has already leaked as much as a sieve.
Several hours ago, keen netizens noticed that “DeepSeek V4.1 Flash-1017” briefly appeared in the DeepSeek model list.
Although the release time was short, it was still caught by those who kept checking for updates.
“1017” precisely corresponds to October 17th, and also follows the consistent approach DeepSeek uses for marking model snapshots with dates.
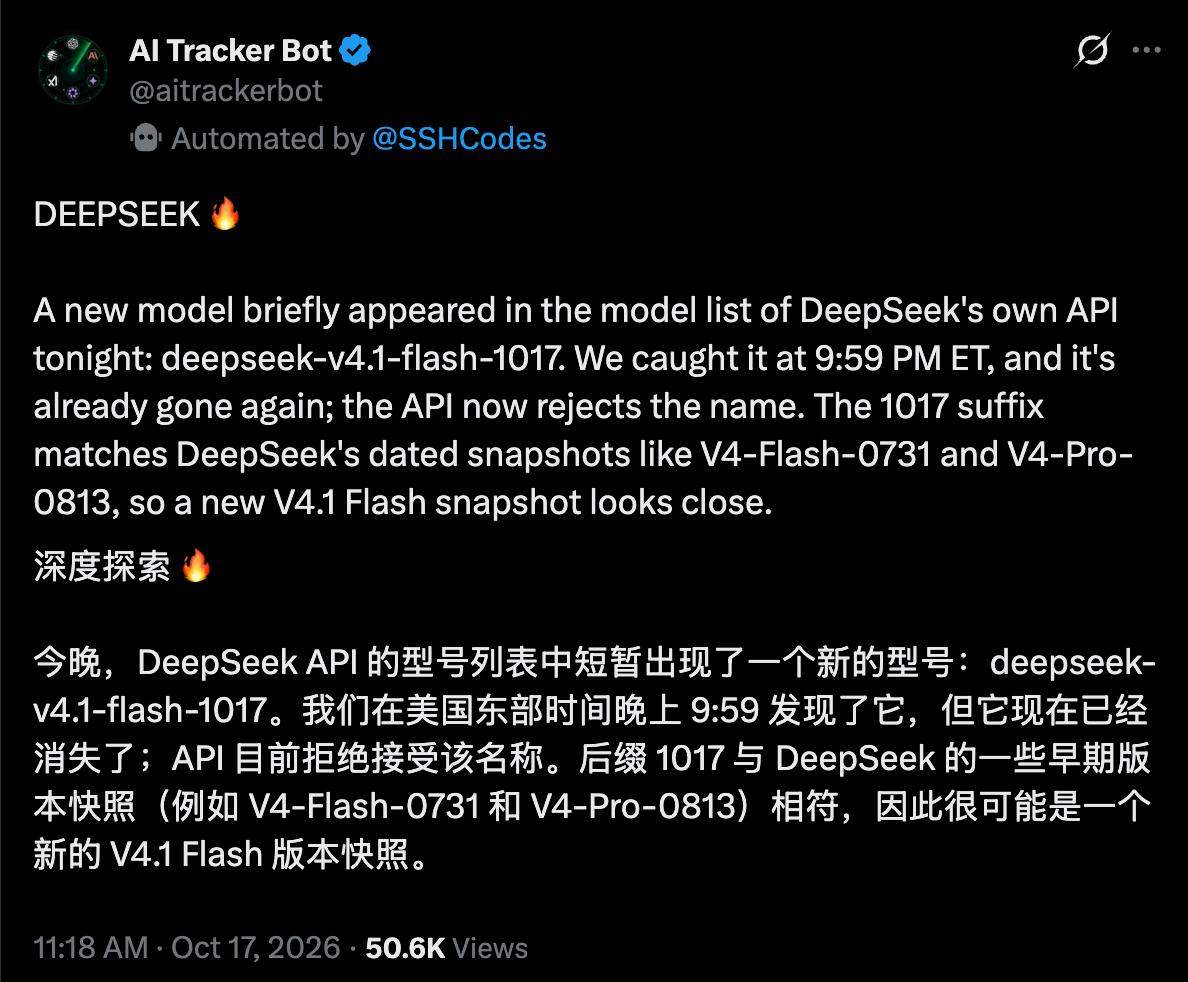
Then, another piece of evidence emerged.
Some netizens found that the system fingerprint returned by the deepseek-flash interface has changed from “
aeb56401ca74e127821c4f9126dcb669” to “e72d3c7f663d3e1383b00b3884cb4501”.
The system fingerprint has changed, which usually means that the model version or deployment configuration of the backend service has been updated.
And after a round of experience, the commonly agreed-upon statement is:
The new model seems smarter, faster, and produces simpler outputs.
The blogger Chetaslua found that the new version on the right produces more detailed images with more realistic lighting effects.
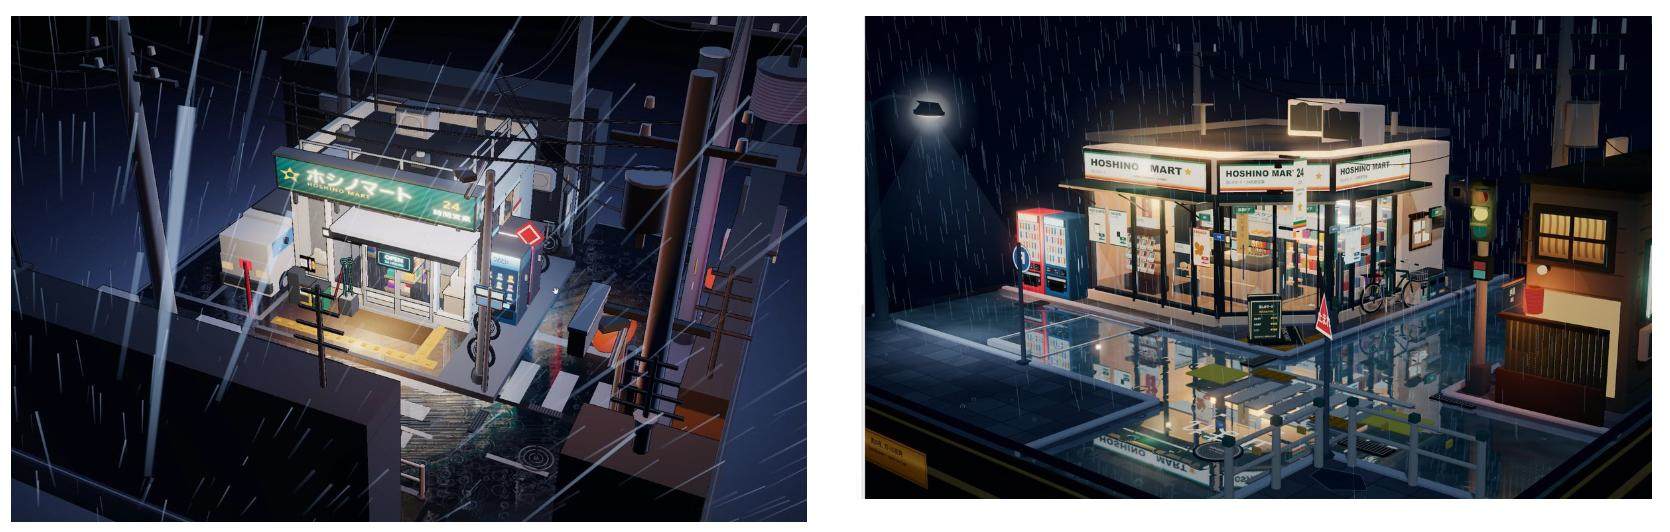
The effect achieved in one sentence is also great, along with a detailed creation process.
The original author said it is more convenient to use than Gemini 4 Argon.
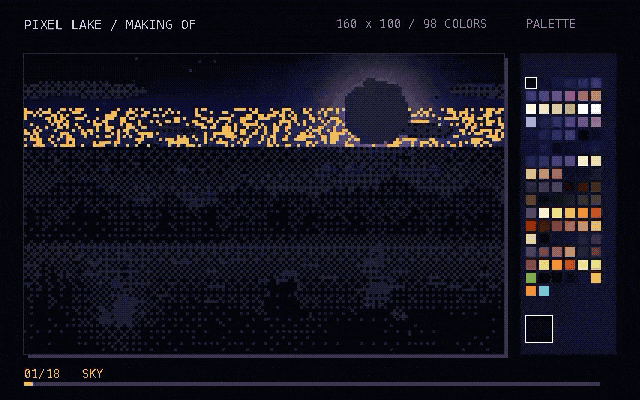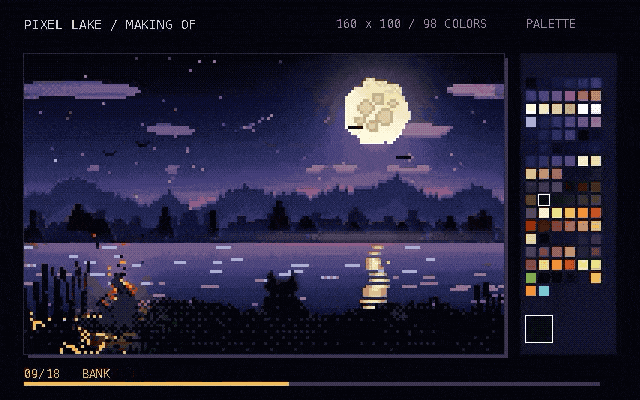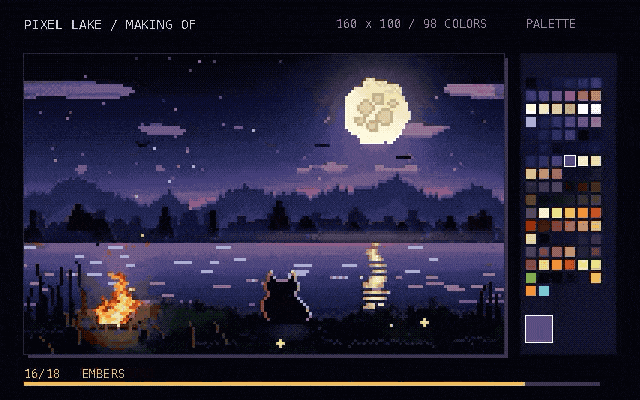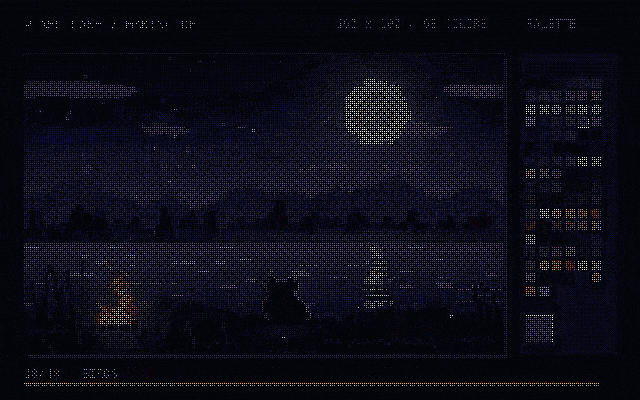
From more multi-modal results, it appears that the new model has enhanced the 3D generation capability.
The several images published by blogger Hakm are quite stunning—just like the impact that GPT-6 Astra had when it was released.
He also quickly created a very classic gunfight game using the model.
Wow! This one’s really worth watching.
The self-developed search API has also been made available
Not only that, this time the big fat fish also provided us with the special tool for the Agent to search online for information.
DeepSeek's self-developed search engine has officially launched two API interfaces: Search and Fetch. The former is used for searching web pages, while the latter is used to read the main content.
Developers can first have the Agent search for information using keywords, then extract the selected web pages into Markdown text, and pass it to the model for further analysis.
The Search API also supports filtering by website, language, and publication time, allowing users to narrow down the scope when looking for the latest news.
The costs of this part of the bill will also be calculated separately based on the number of successful requests:
Extremely low – 5 yuan for every 1,000 successful requests, and only half a cent for a single use. There is no charge if the request fails, no results are found, or if it times out.
Currently, users can call the DeepSeek API when using DeepSeek Harness, Claude Code, or Codex. Moreover, for a limited time until November 1st, it is free.
To be honest, that value-for-money king is back again.
DeepSeek enters another Liang Sheng cycle.
HuggingFace:
https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
ModelScope:
https://modelscope.cn/models/deepseek-ai/DeepSeek-V4.1-Flash-1017
Reference links:
[1]
https://mp.weixin.qq.com/s/X-5kbBkedQ5Oct9byUunag
[2]
https://x.com/aitrackerbot/status/2111295736411300047
[3]
https://x.com/yugen_matuni/status/2111336985554227345
[4]
https://x.com/hakmgpt/status/2111314470433947988
[5]
https://x.com/hakmgpt/status/2111314427416895798
[6]
https://api-docs.deepseek.com/guides/search/