
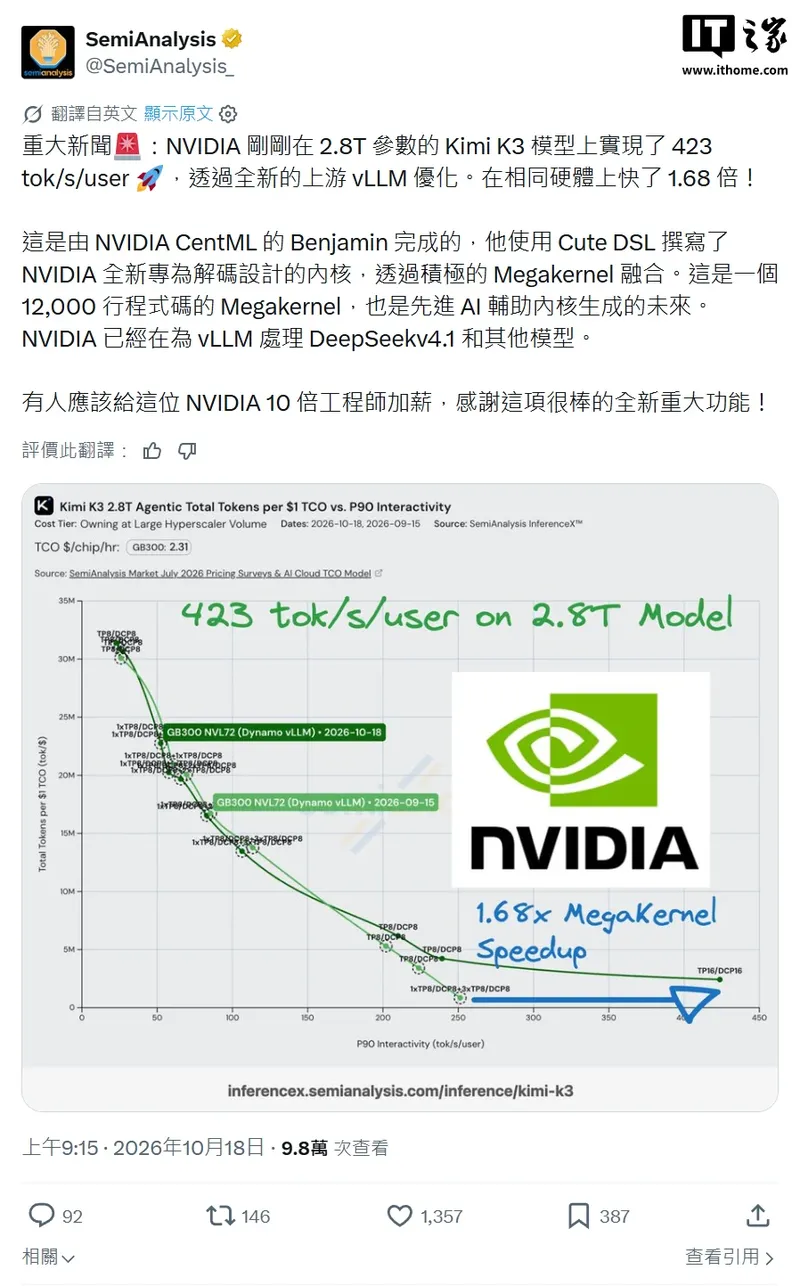
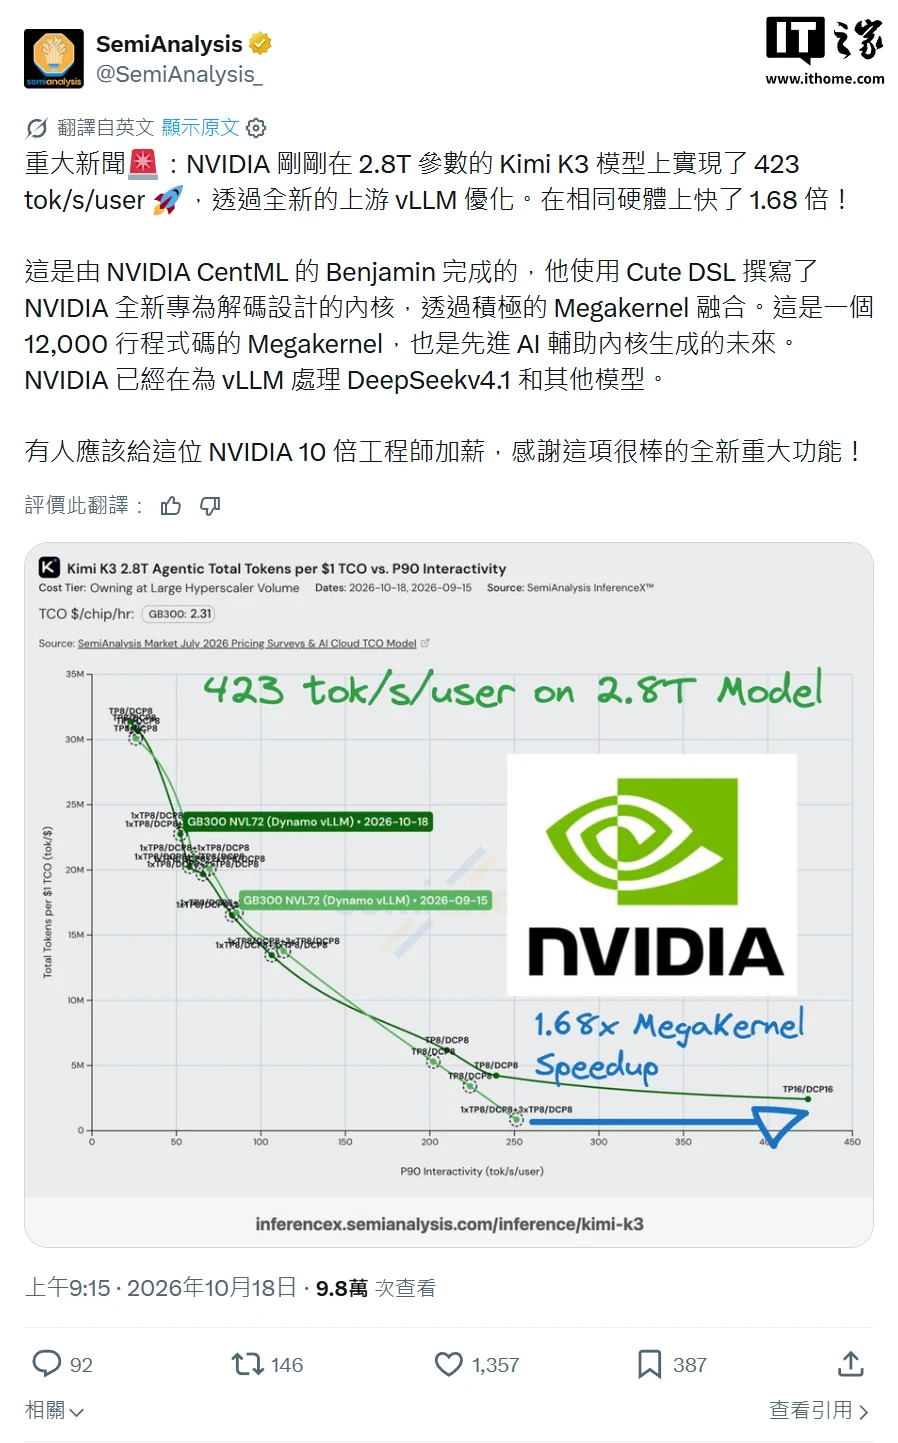
IT Home On October 18, a research firm SemiAnalysis reported that NVIDIA’s upstream vLLM optimization has enabled the Kimi K3 model with 2.8 trillion parameters to achieve a reasoning speed of 423 tok/s/user. This represents a 1.68 times improvement in performance compared to the same hardware (GB300 NVL72).
According to the introduction, this optimization was completed by Benjamin, an engineer at NVIDIA CentML. It uses large-scale Megakernel integration and Cute DSL to write the new decoding kernel specifically developed by NVIDIA. This Megakernel contains 12,000 lines of code, representing the future direction of AI-assisted generation of advanced computing kernels. NVIDIA improved the inference speed of the Kimi K3 model by 1.68 times through optimization.
IT Home notes that in addition to this, NVIDIA is also working on the optimization of other models such as DeepSeek V4.1 for vLLM.