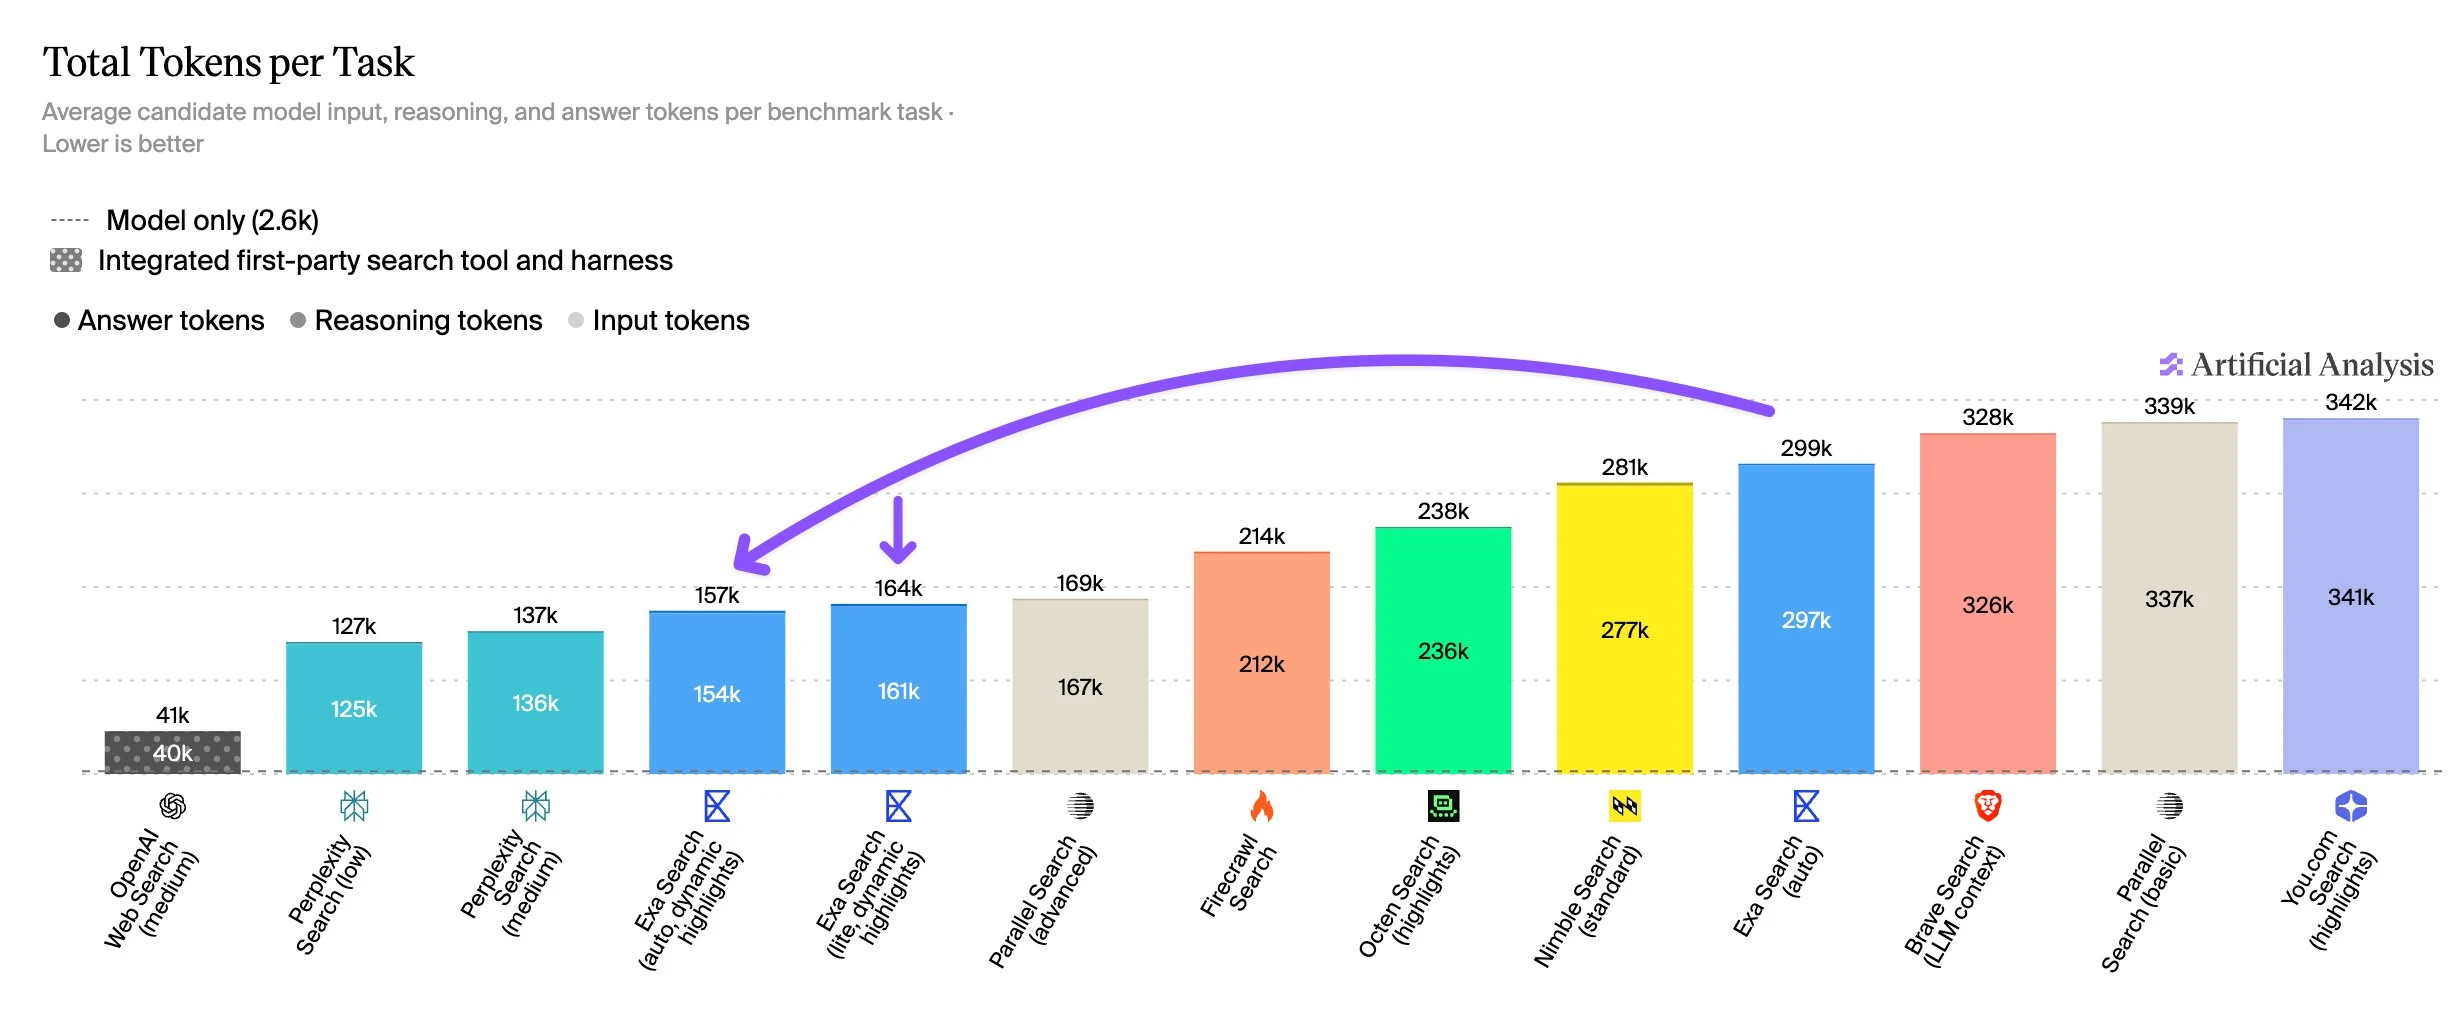
Total Tokens per Task measures the model's input, reasoning and output tokens
Exa (auto, Dynamic Highlights) uses 157k tokens per task, 47% fewer than auto with standard highlights (299k). Exa (lite, Dynamic Highlights) uses 164k tokens, a 45% reduction
Dynamic Highlights reduces the amount of search content returned to the model, lowering token consumption and model inference costs. Among Search APIs, only Perplexity (low, 127k) and Perplexity (medium, 137k) use fewer tokens per task